Lecture 14
Duke University
STA 199 - Fall 2026
October 19, 2026
1️⃣ First, fill out peer evaluations for your teammates on TEAMMATES. Check your email for a link to the survey. It’s due tonight at 11:59 pm.
2️⃣ Then, fill in the blank below:
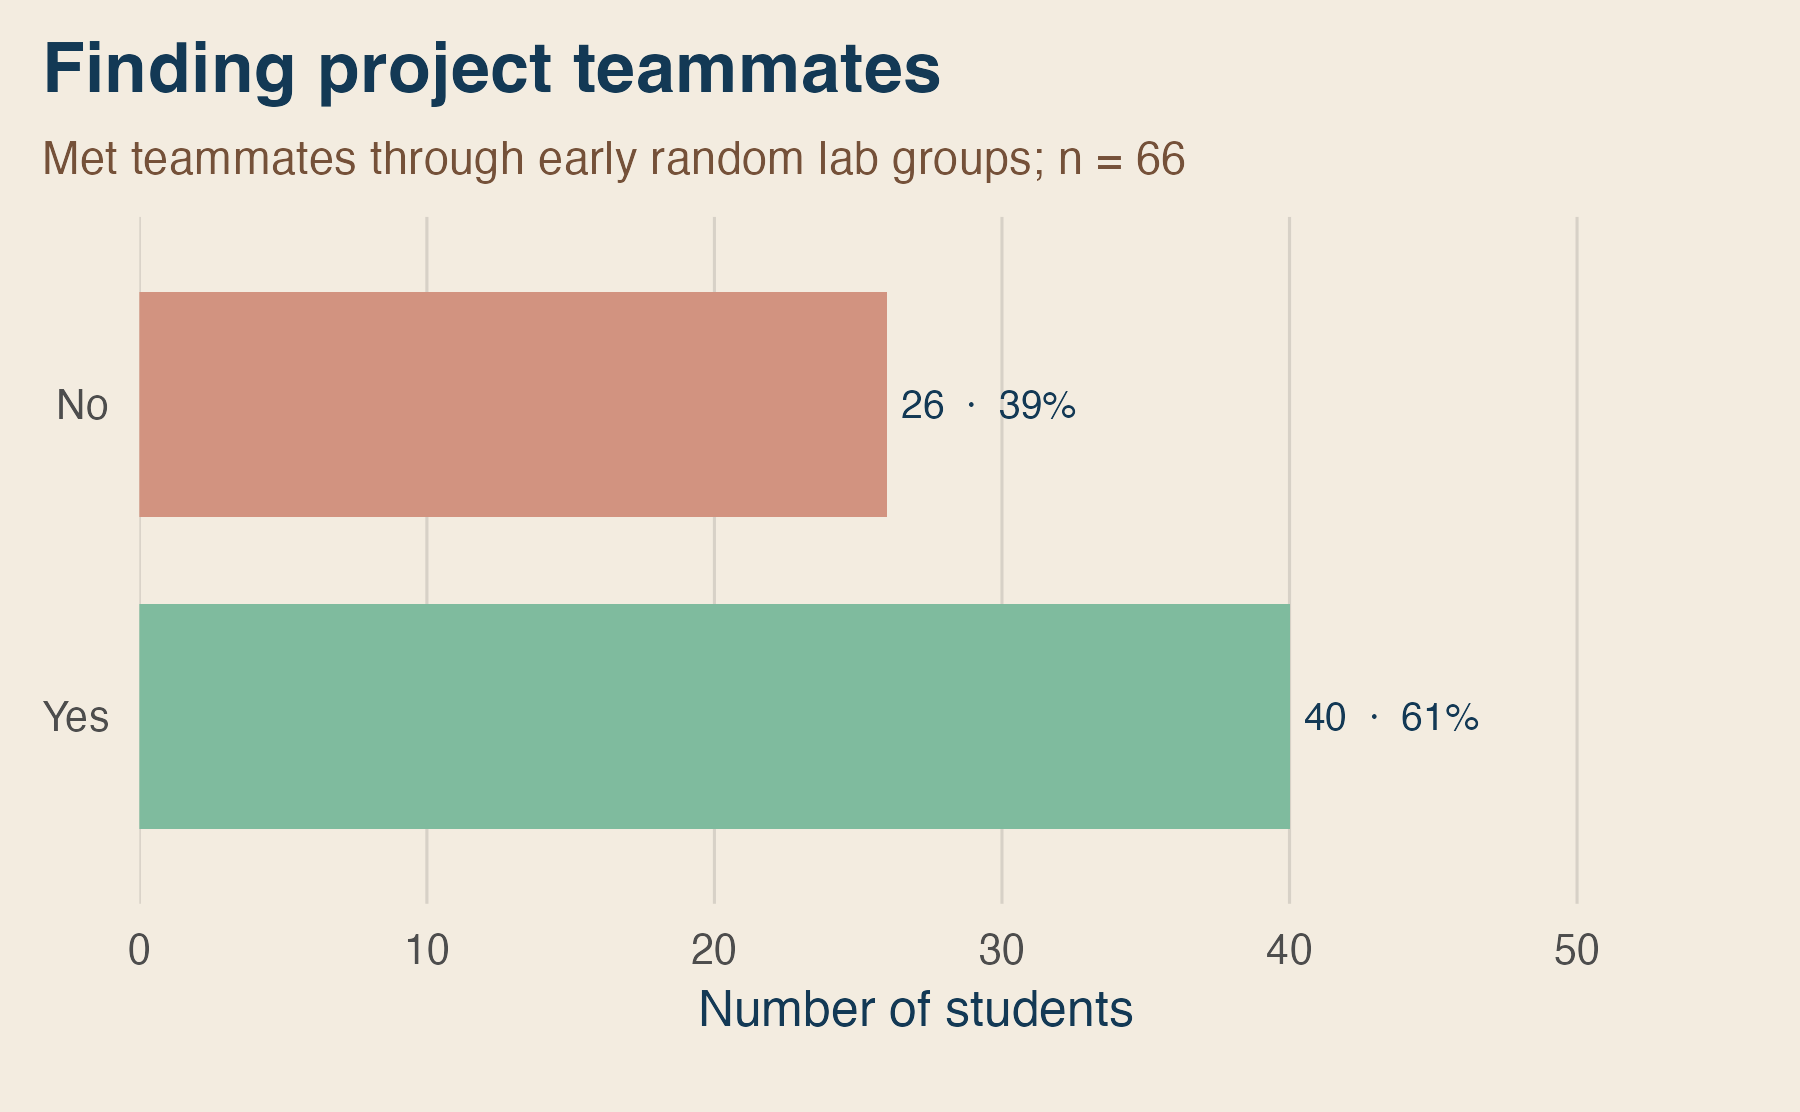
We will meet (or already met) as a team to make progress on our projects ______.

Go to wooclap.com and use the code UDHRUEH.
Do not forget to fill out peer evaluations for your teammates on TEAMMATES!
Make LOTS of progress on your project before Thursday’s lab, where you’ll provide (and receive) peer review to (from) another team in your lab.
Office hours change: For this week only, my office hours will be on Friday, 2 - 3:30 pm (at my office – Old Chem 211C – as usual).
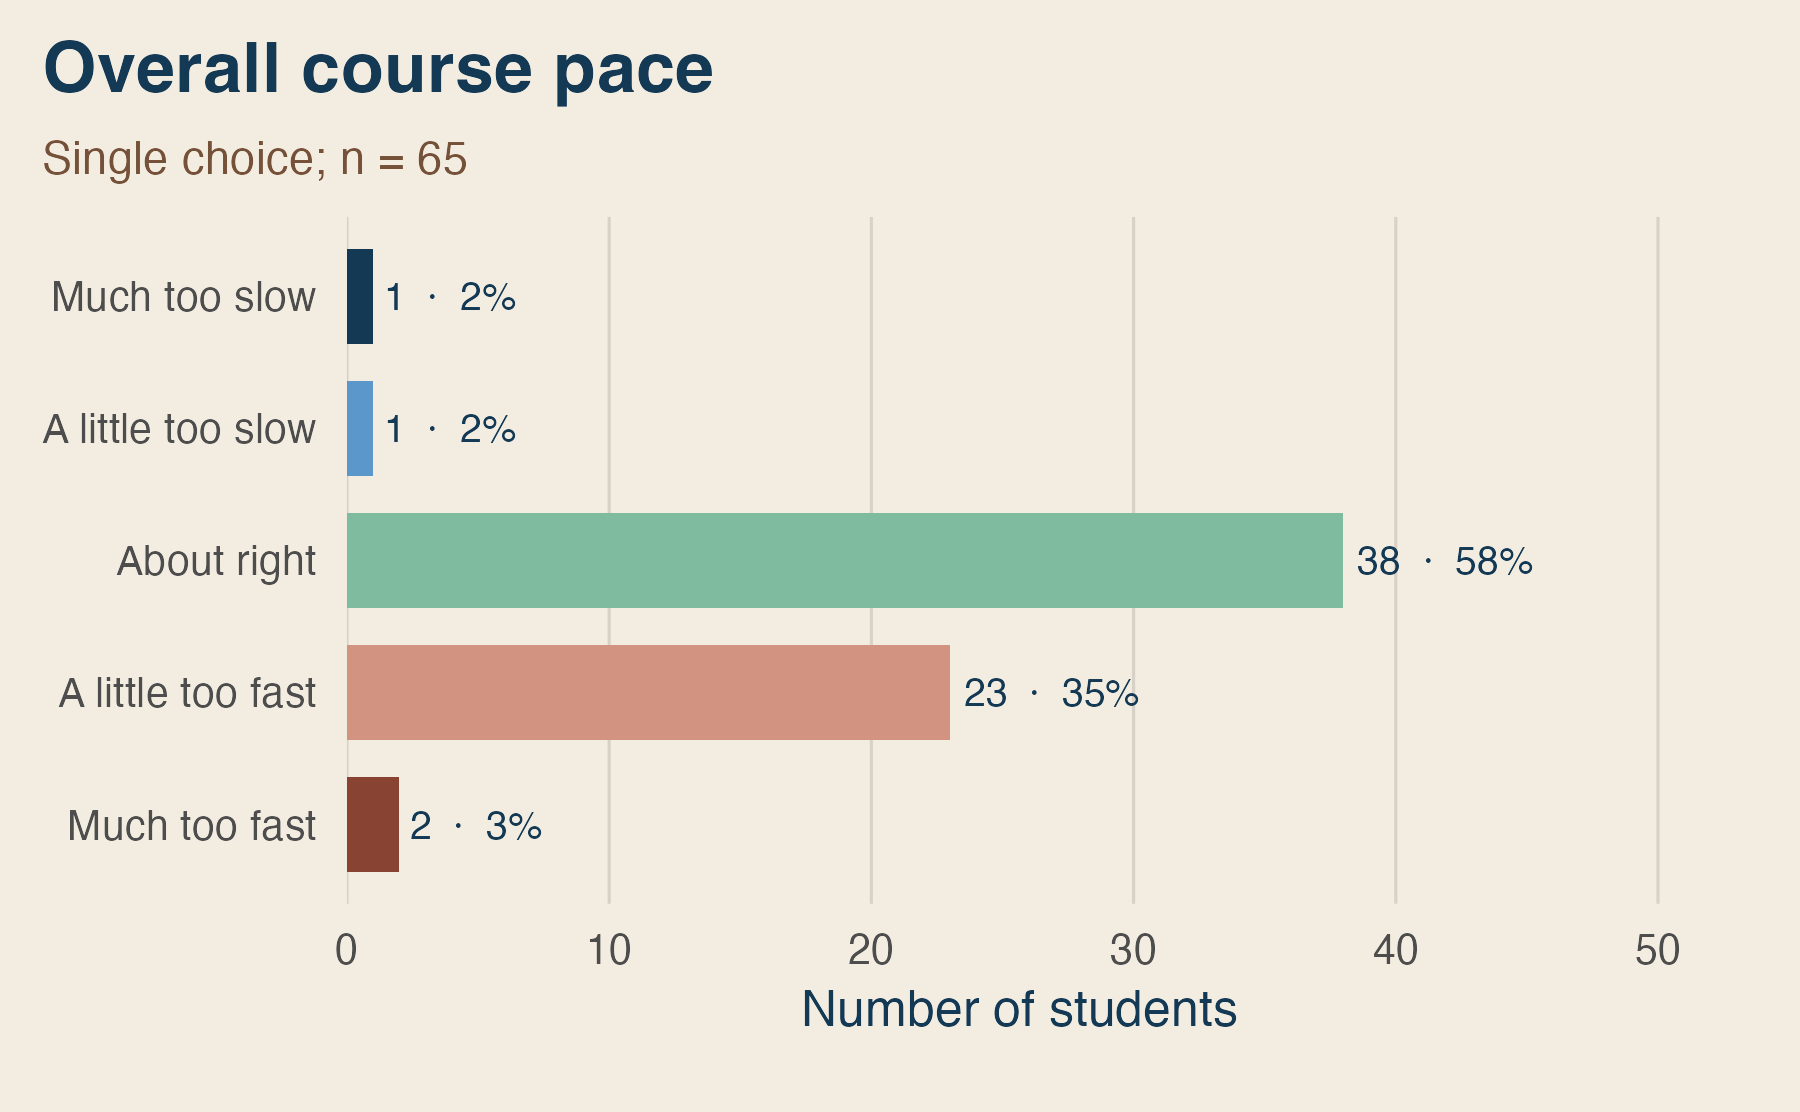
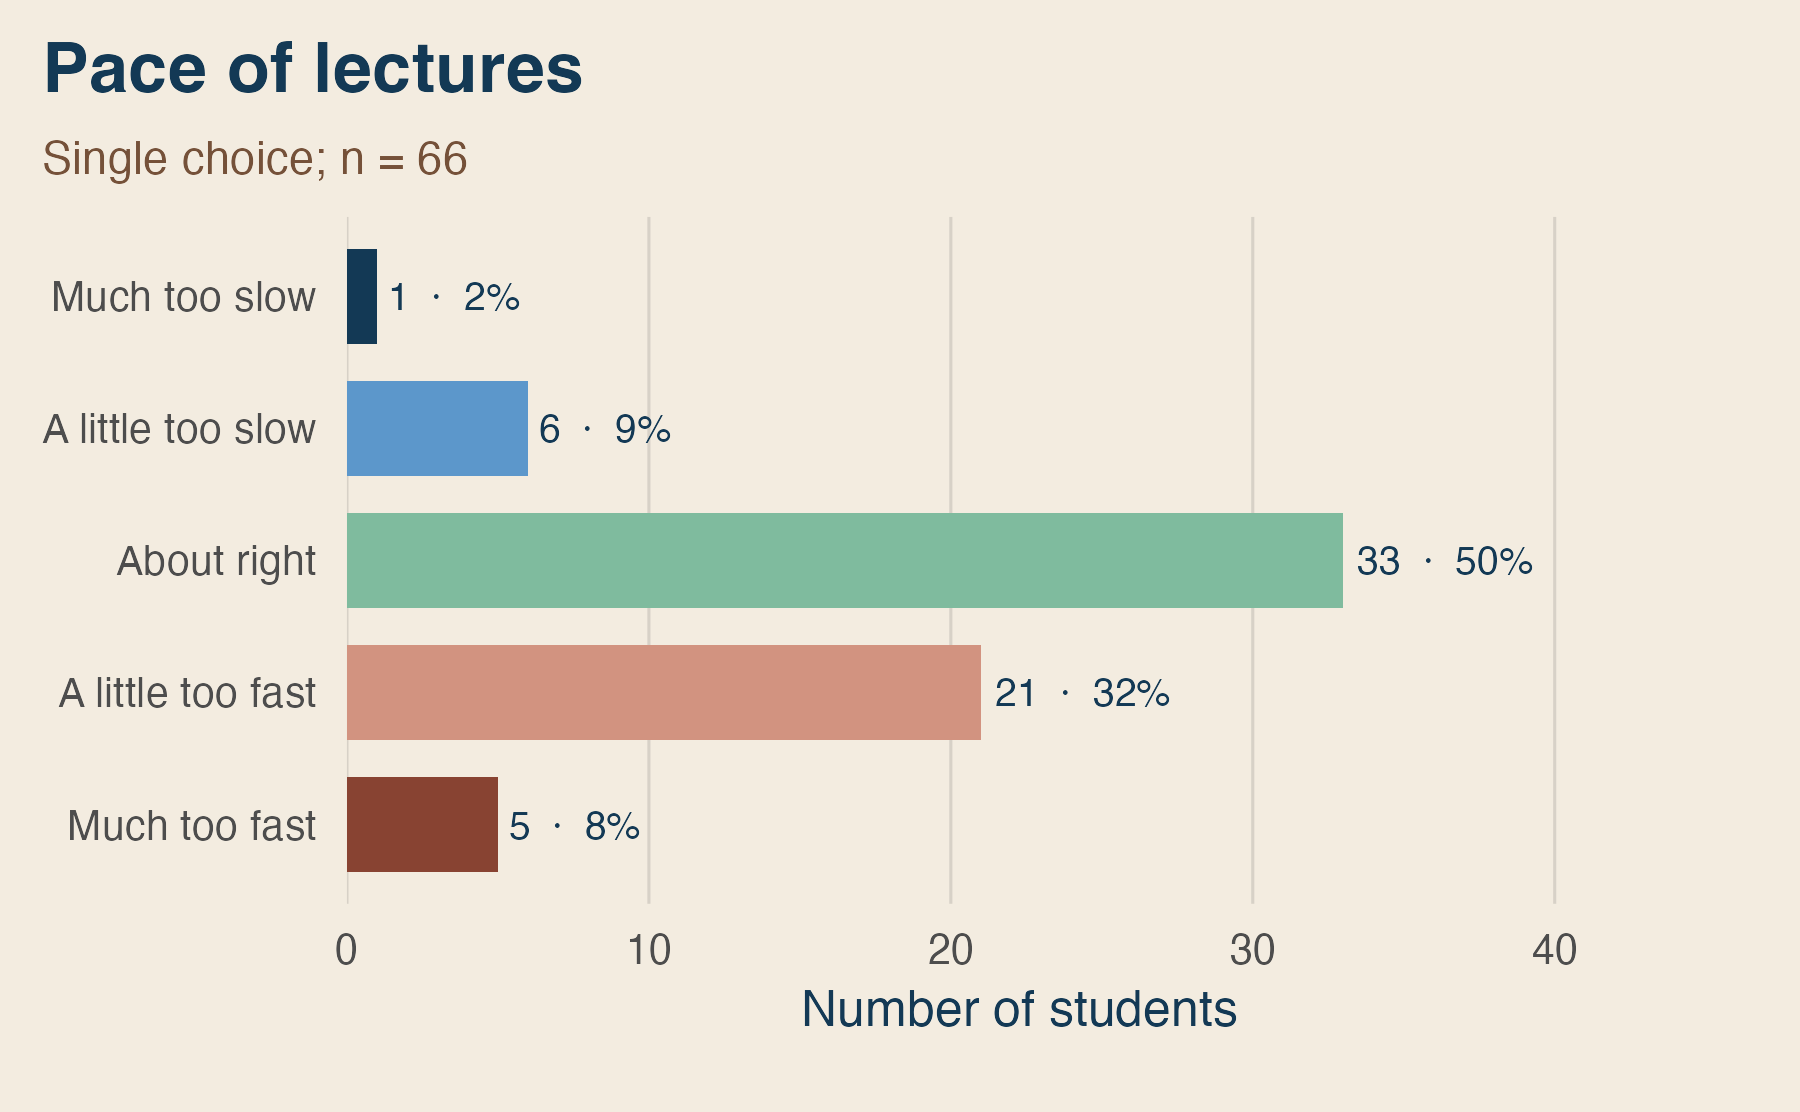
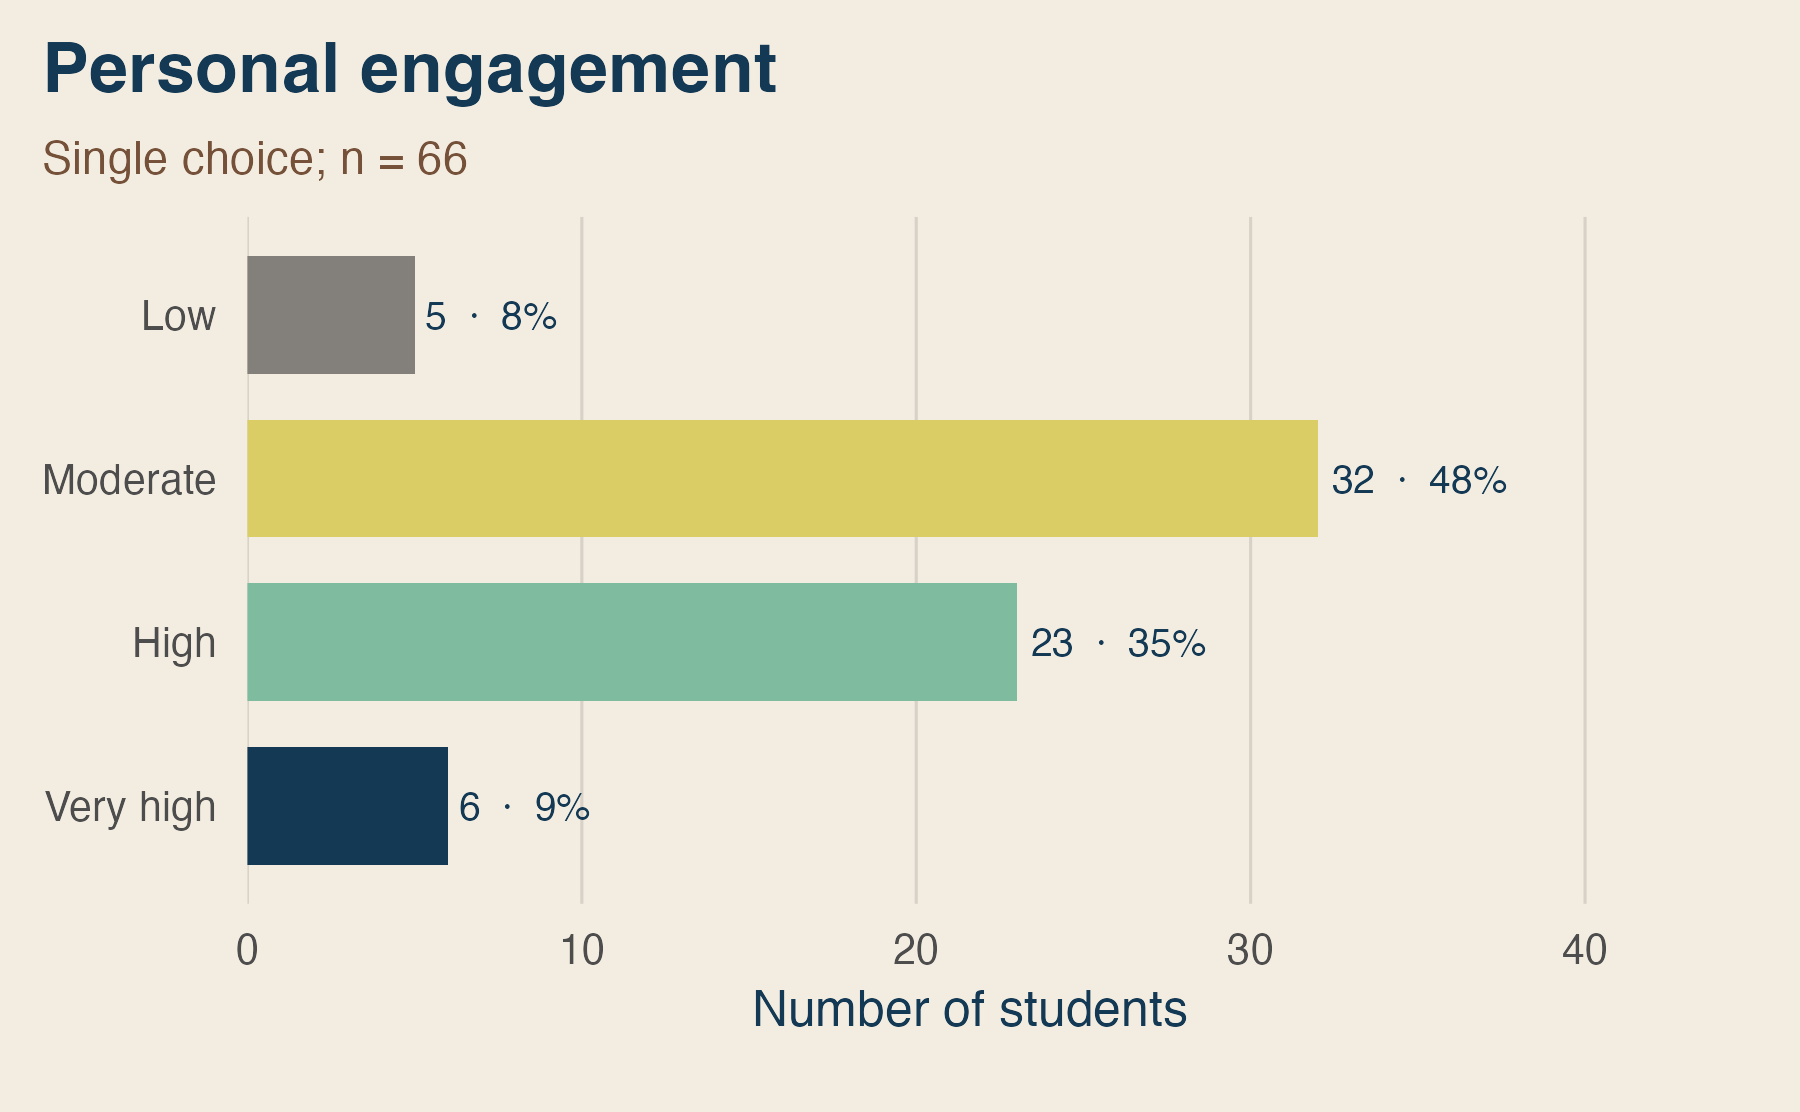
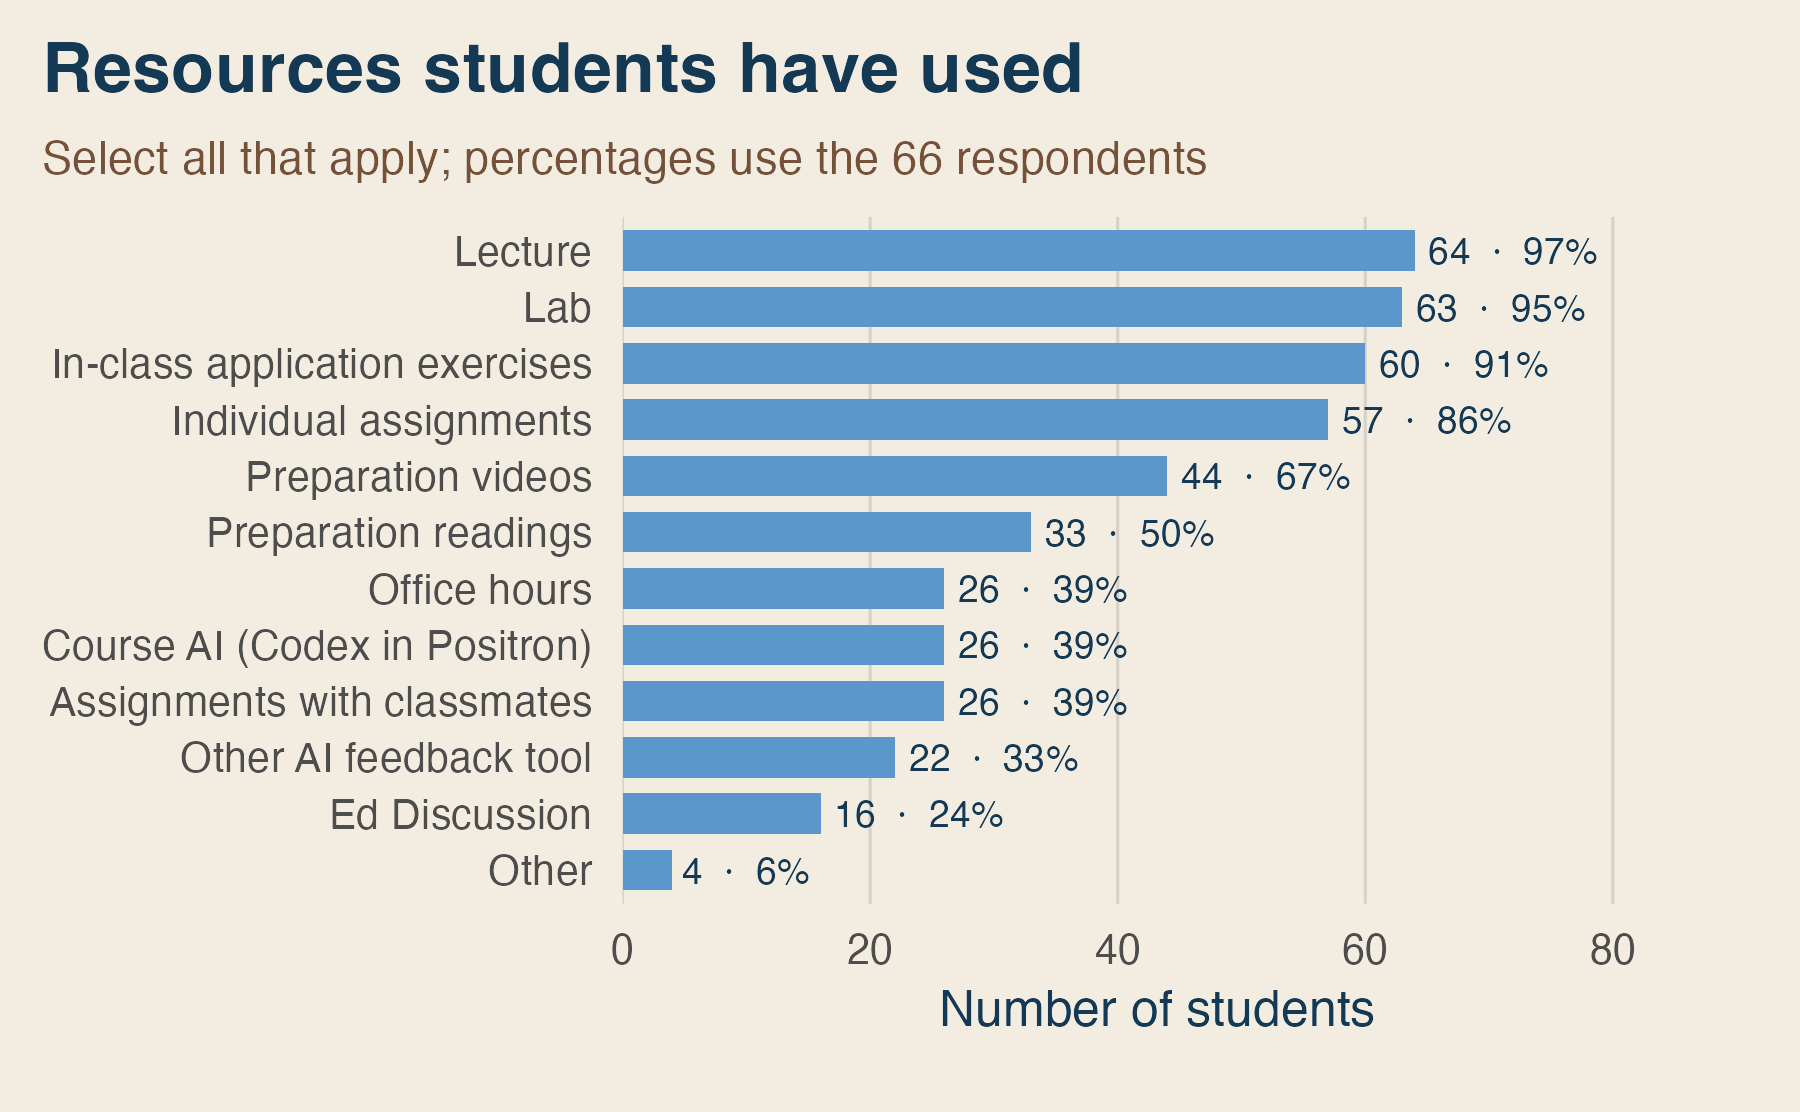
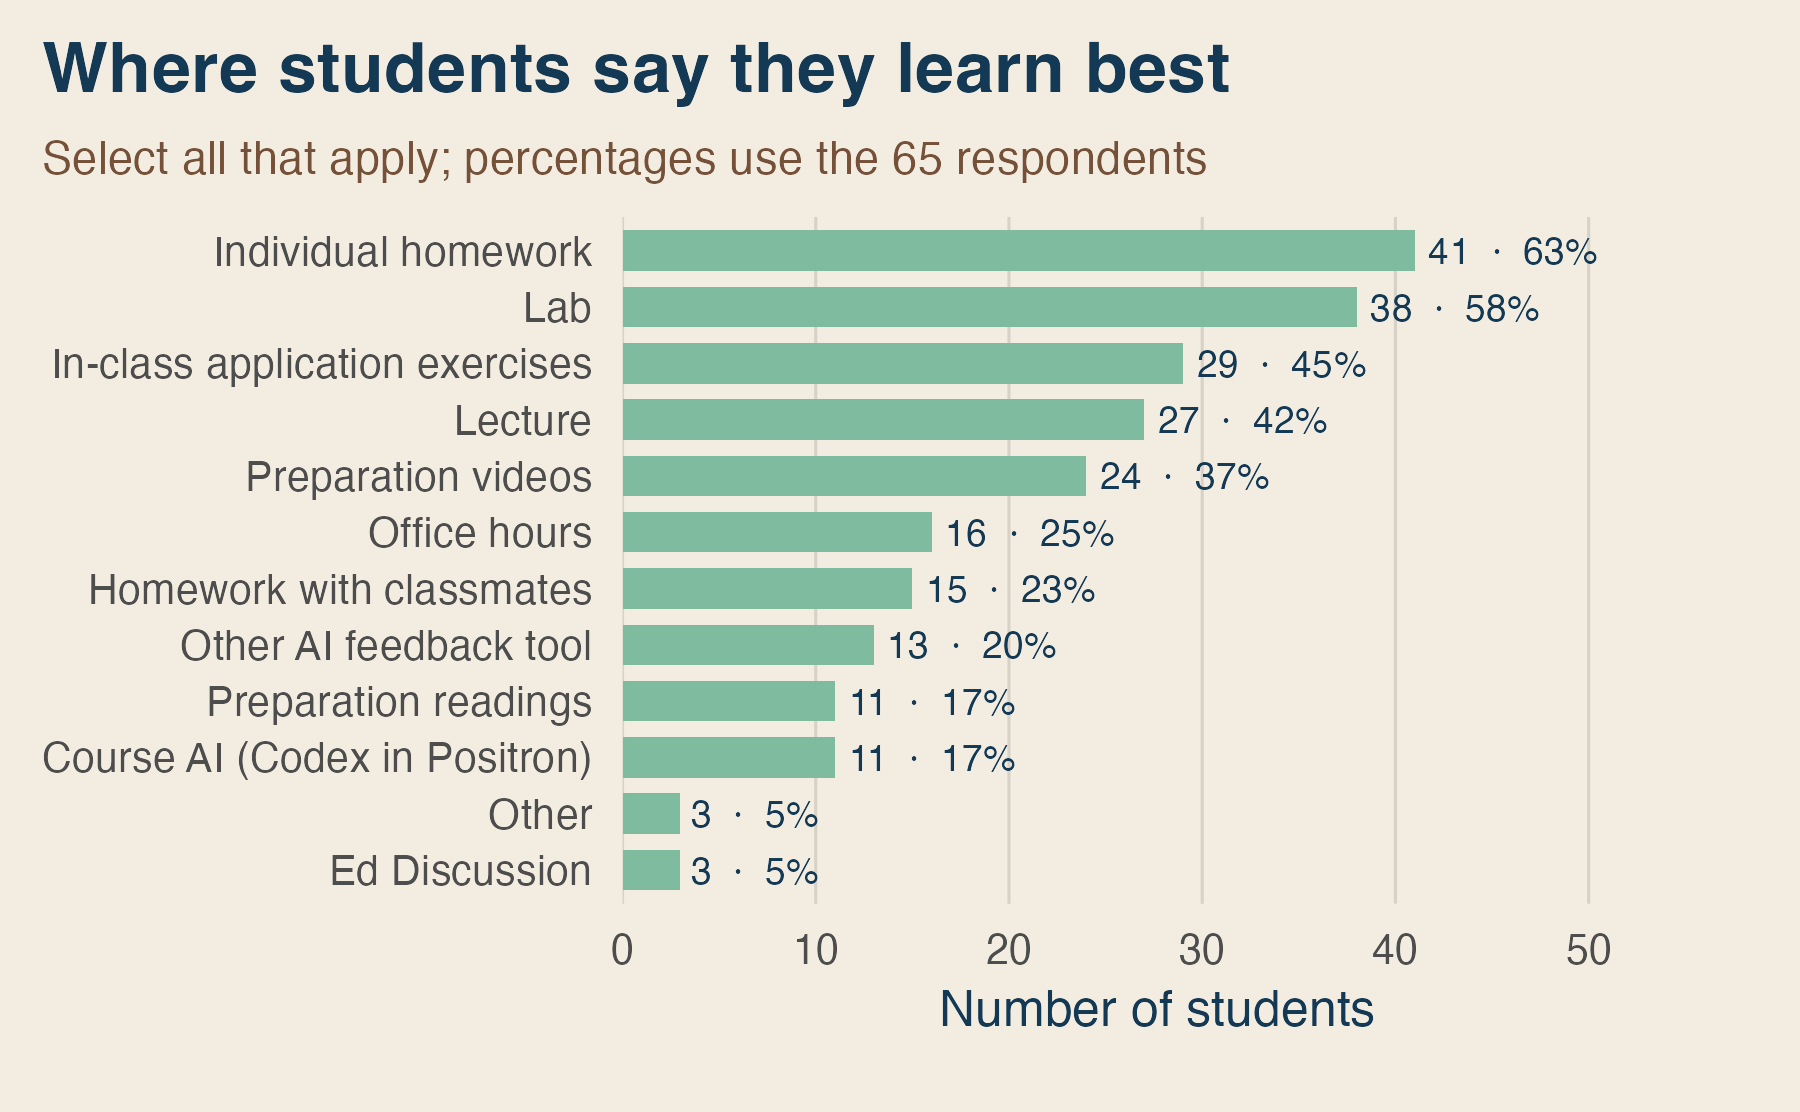
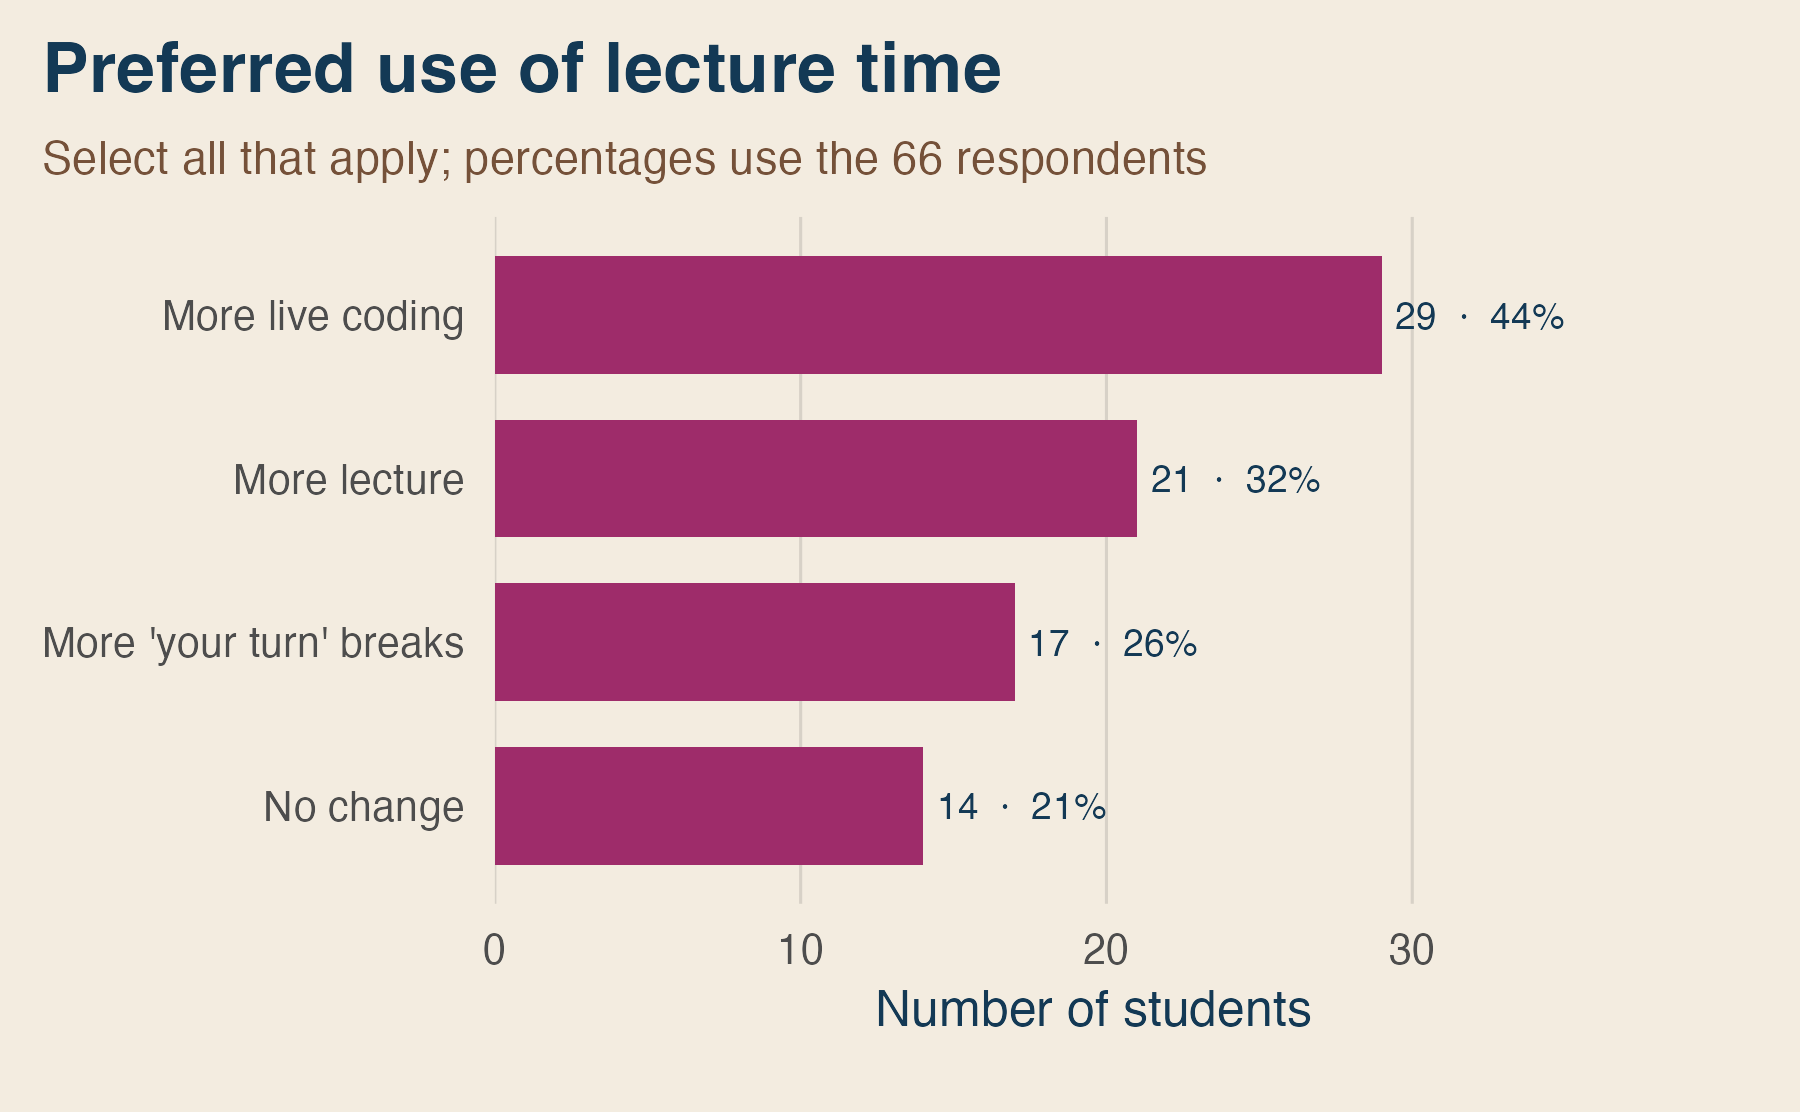
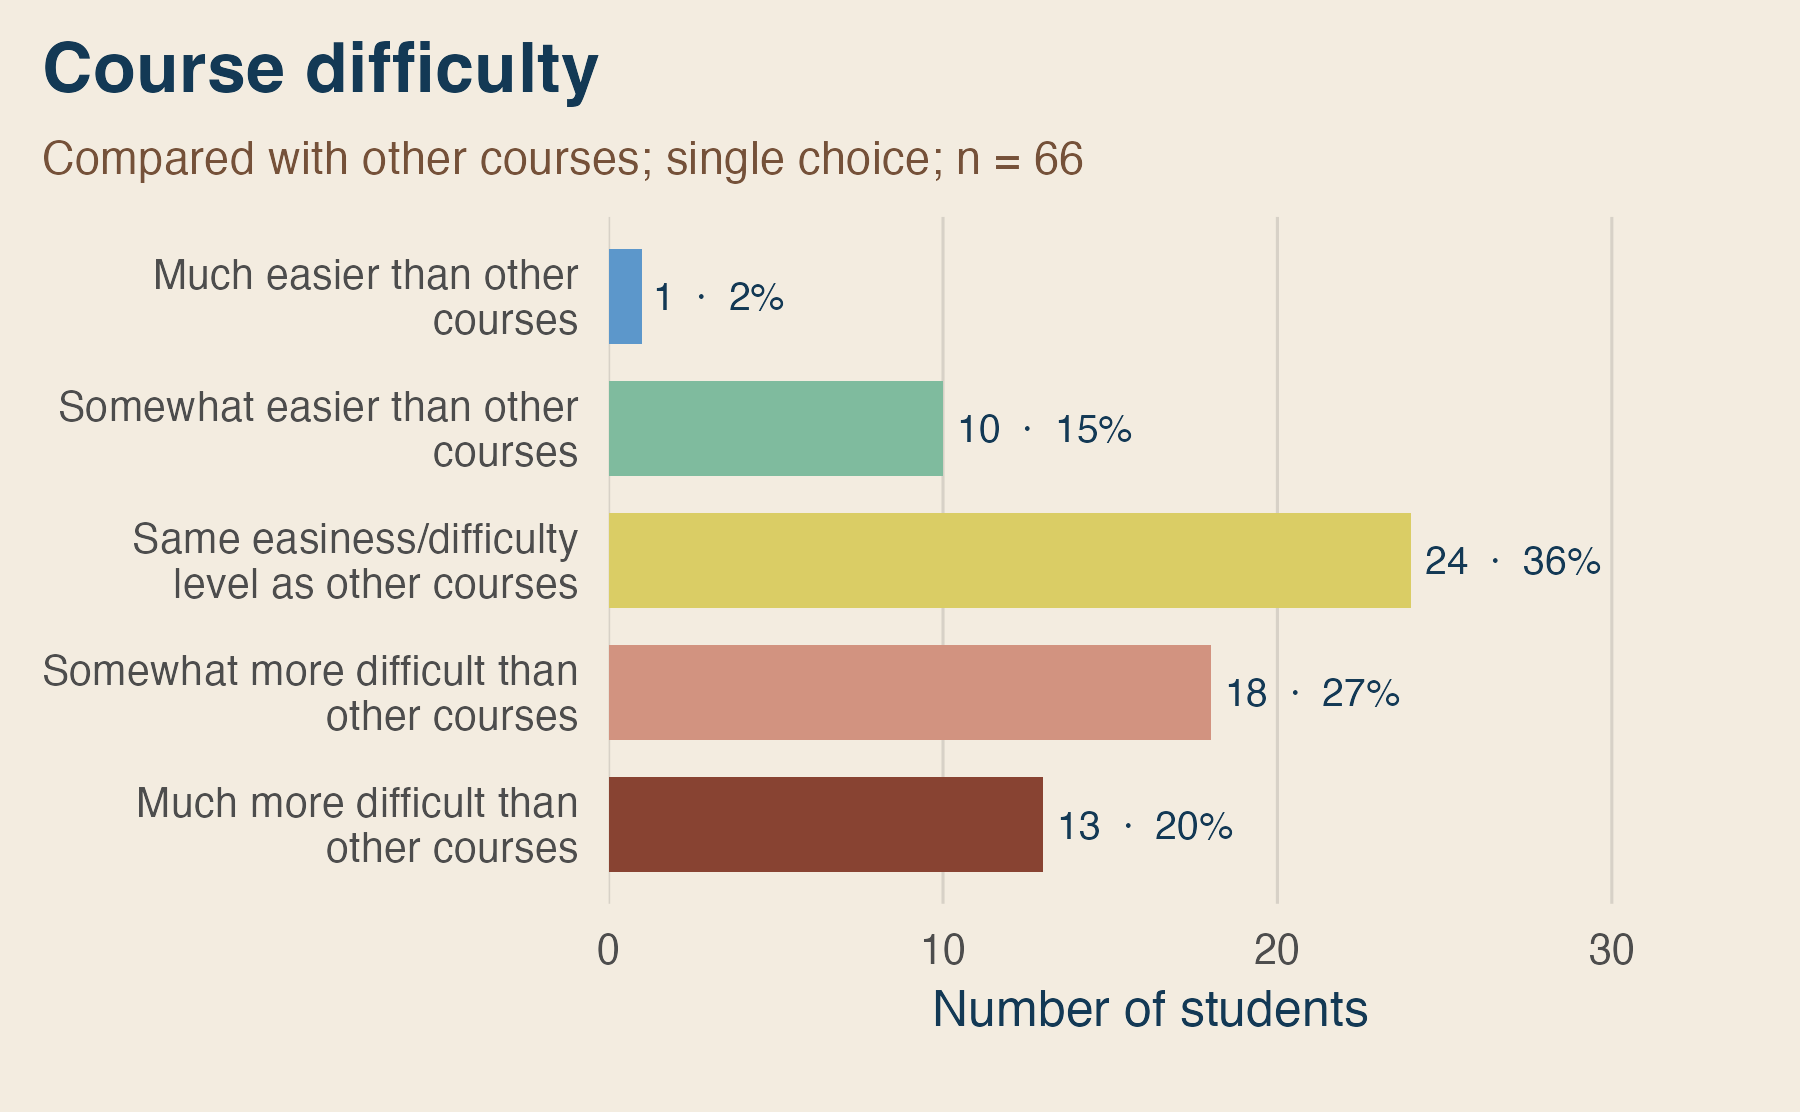
Thank you to the 66 of you who provided feedback! ♥️
32 of 66 students entered text; this excludes entries such as no comment or N/A.
These are aggregate, paraphrased themes; no individual response is quoted.
35 of 66 students entered text; this excludes entries such as no comment or N/A.
These are aggregate, paraphrased themes; no individual response is quoted.
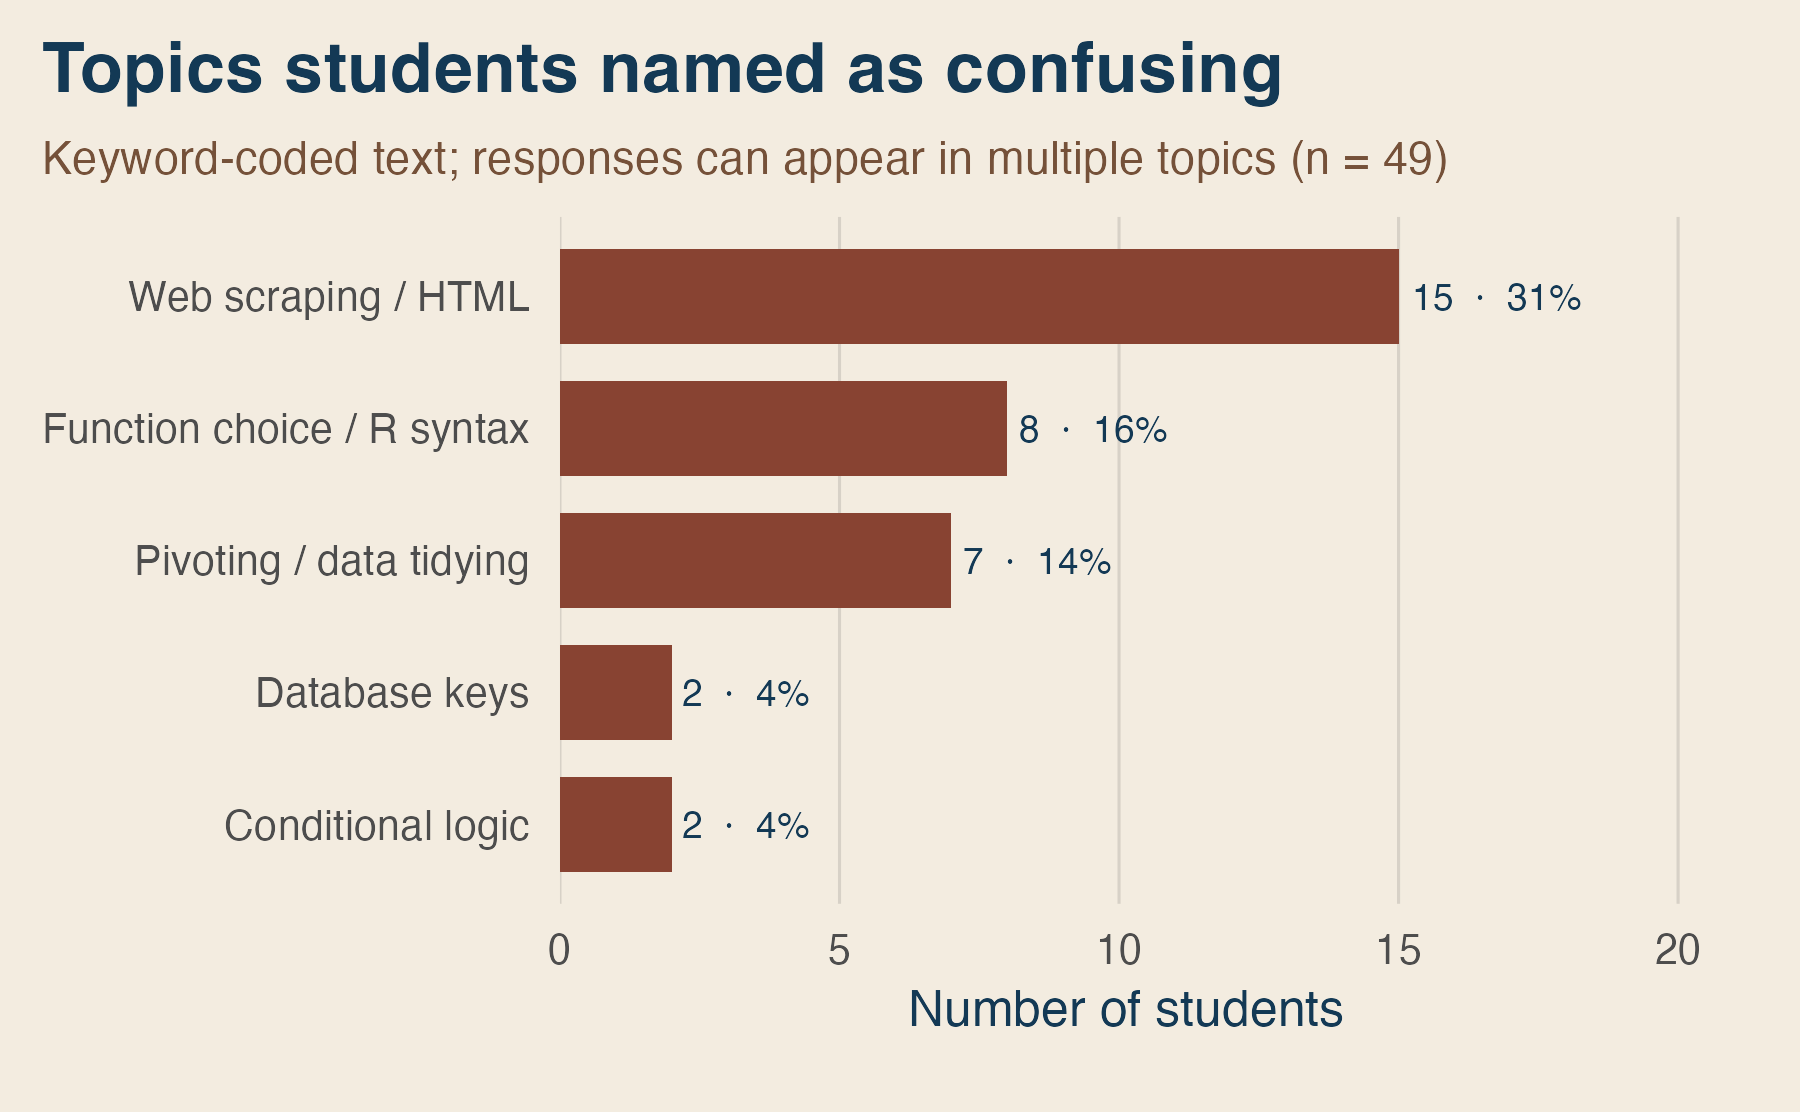
Several students said they were not confused about a particular topic.
49 of 66 students entered text; this excludes entries such as no comment or N/A.
These are aggregate, paraphrased themes; no individual response is quoted.
19 of 66 students entered text; this excludes entries such as no comment or N/A.
These are aggregate, paraphrased themes; no individual response is quoted.
Data do not speak for themselves. They require an interpretive lens, not all of which are created equal.
The practice of data science is not ethically neutral or value-free.
What is your username on… GitHub, LinkedIn, Reddit, Instagram, TikTok, other social media platforms, online dating services, etc.?
Suppose you create a profile on a social media site and share your personal information on your profile. Who else gets to use that data – companies the social media company has a connection to? companies the social media company sells your data to? researchers?

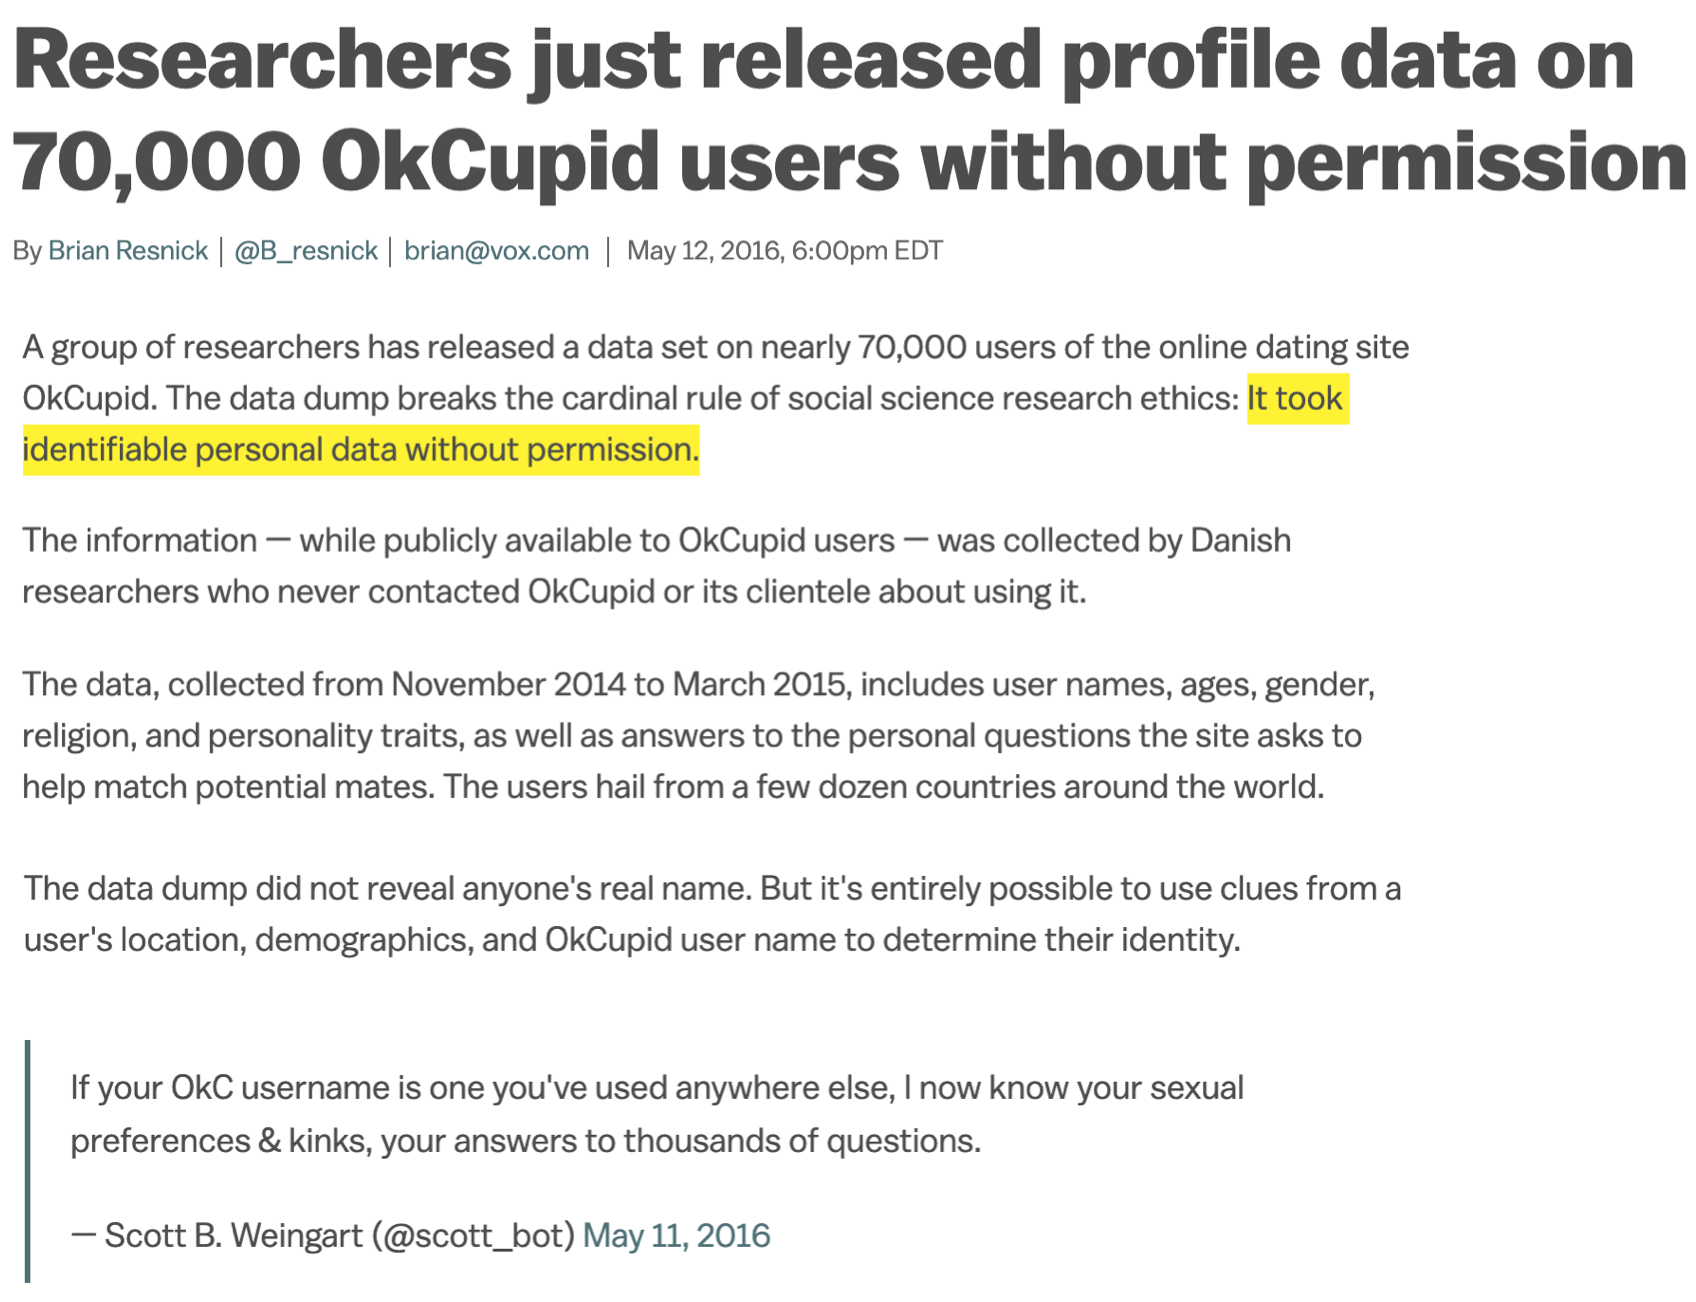
In 2016, researchers published data from roughly 70,000 OkCupid profiles, including usernames, political views, drug use, and intimate sexual details.
Names and photos were excluded, but usernames and other details made re-identification possible.
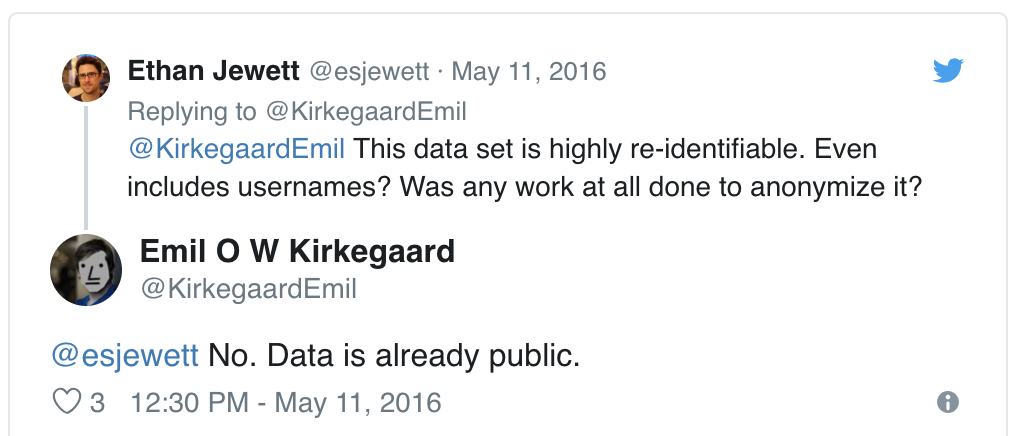
Does public availability imply consent to collect and republish data at scale?
What are some things you know about how car insurance rates are set?
Do you drive a car with “smart” features?

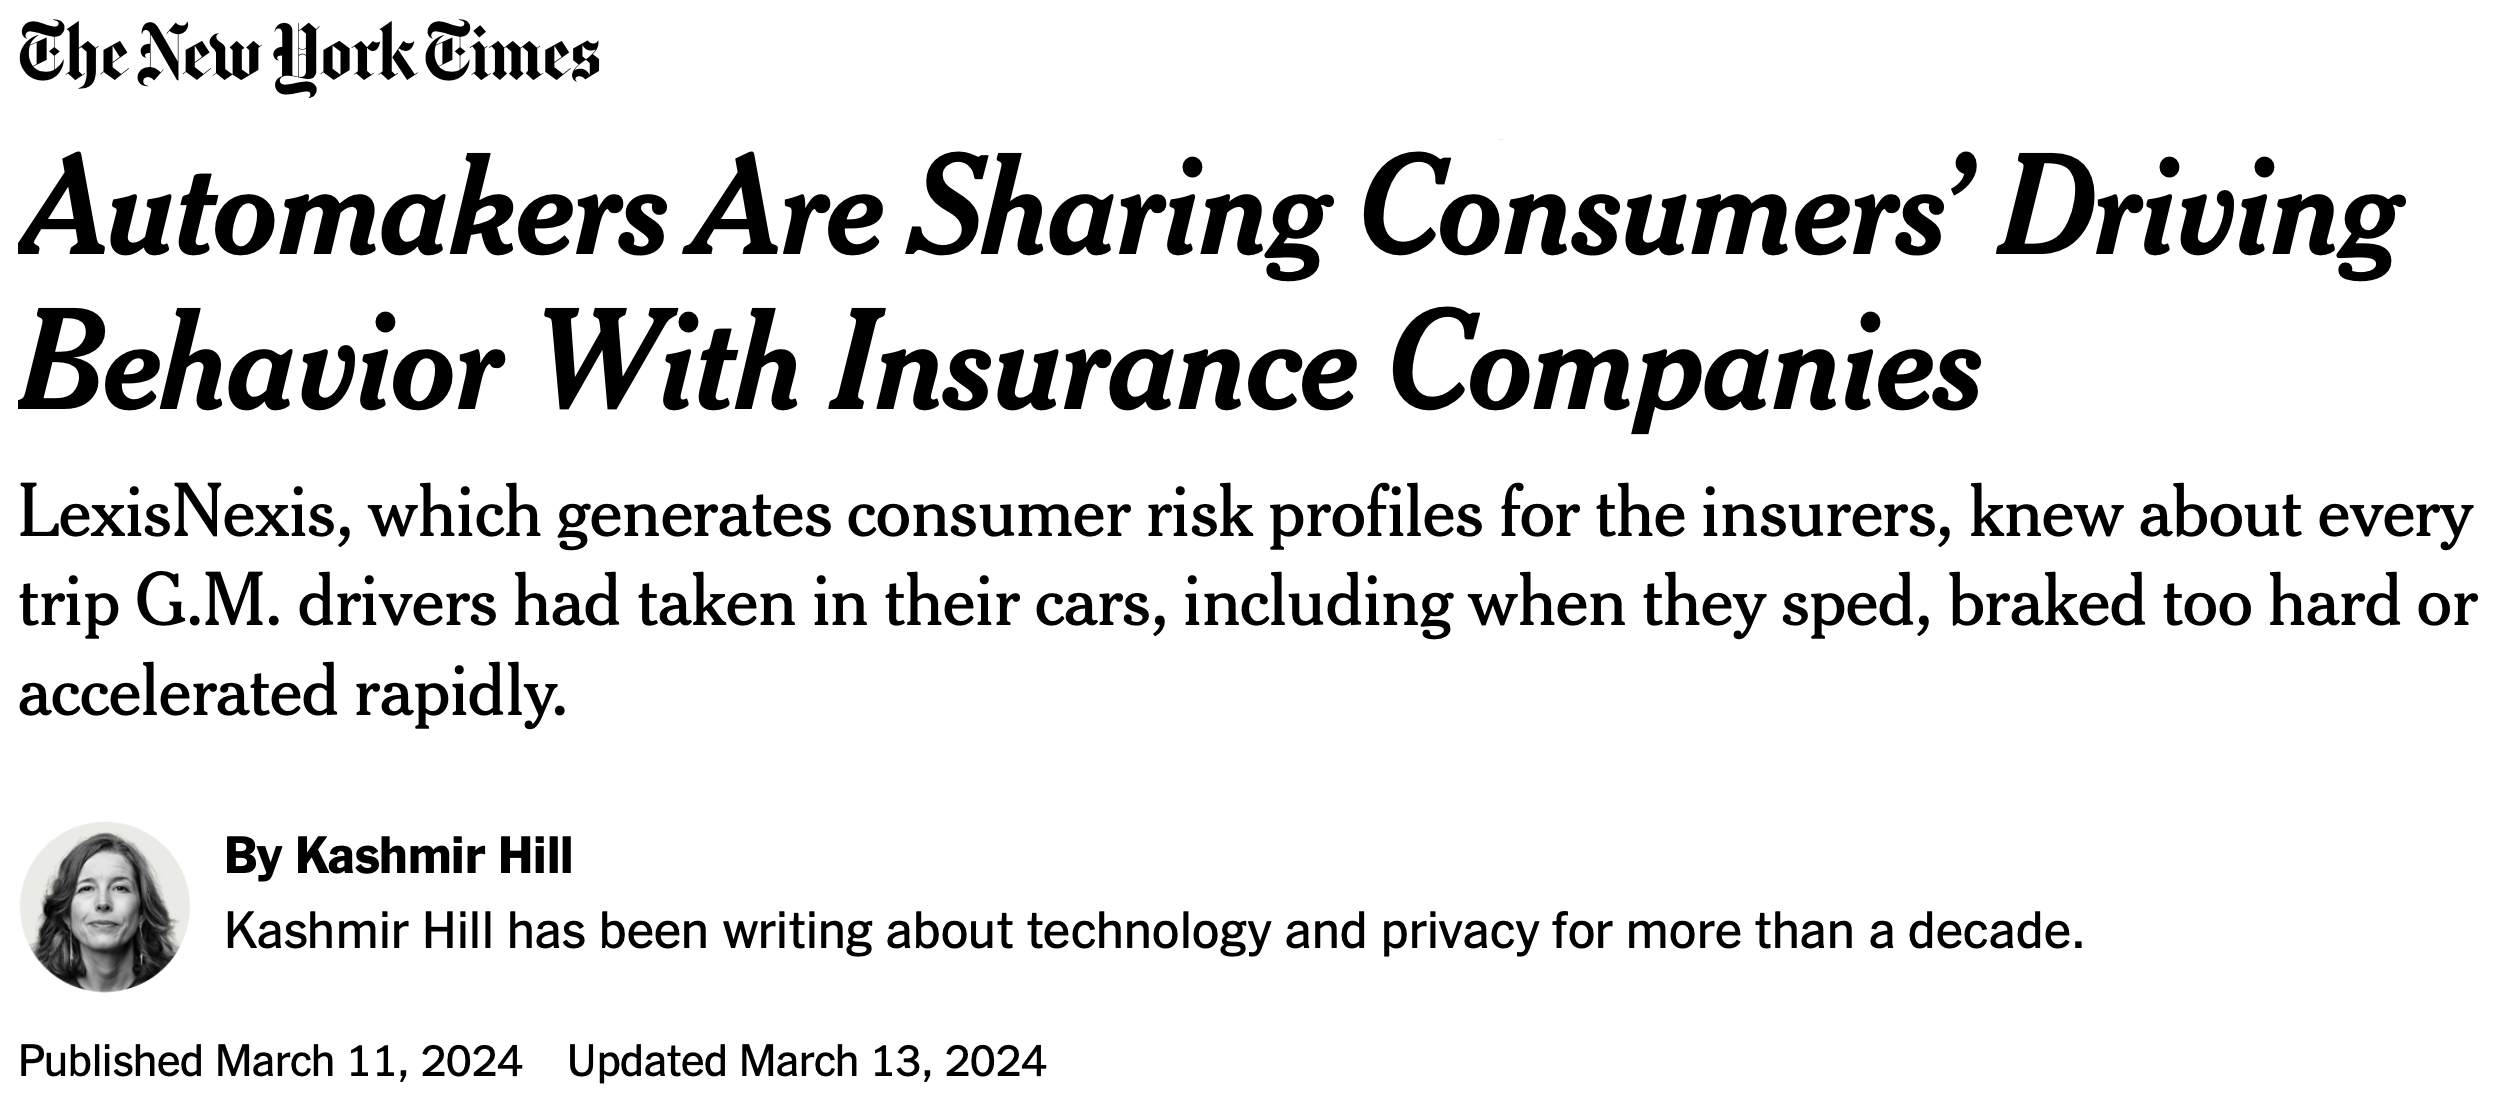
According to an FTC complaint, GM and OnStar collected precise location and driving behavior data from millions of vehicles—sometimes as often as every three seconds.
The data included hard braking, late-night driving, and speeding.
GM sold the data to consumer reporting agencies, where insurers used it to deny coverage or set rates.
The proposed order required affirmative consent, access and deletion rights, and an option to limit collection.
You activate a feature marketed as helping you assess your driving habits. What other uses of those data would require new consent?
Have you ever done a direct-to-consumer DNA testing like 23andMe or AncestryDNA?
In 2023, attackers used credential stuffing—trying usernames and passwords stolen in unrelated breaches—to log into about 14,000 23andMe accounts. Since accounts were connected to many other users through DNA Relatives and Family Tree, the attackers could access profile information associated with approximately 6.9 million people.
Exposed information varied but could include names, birth years, locations, ancestry or ethnicity, genetic relationships, family trees, and, for some users, health reports or raw genetic data.
Genetic data is unusually sensitive, permanent, and shared: exposing one person’s information can also reveal information about relatives who never consented to the service.

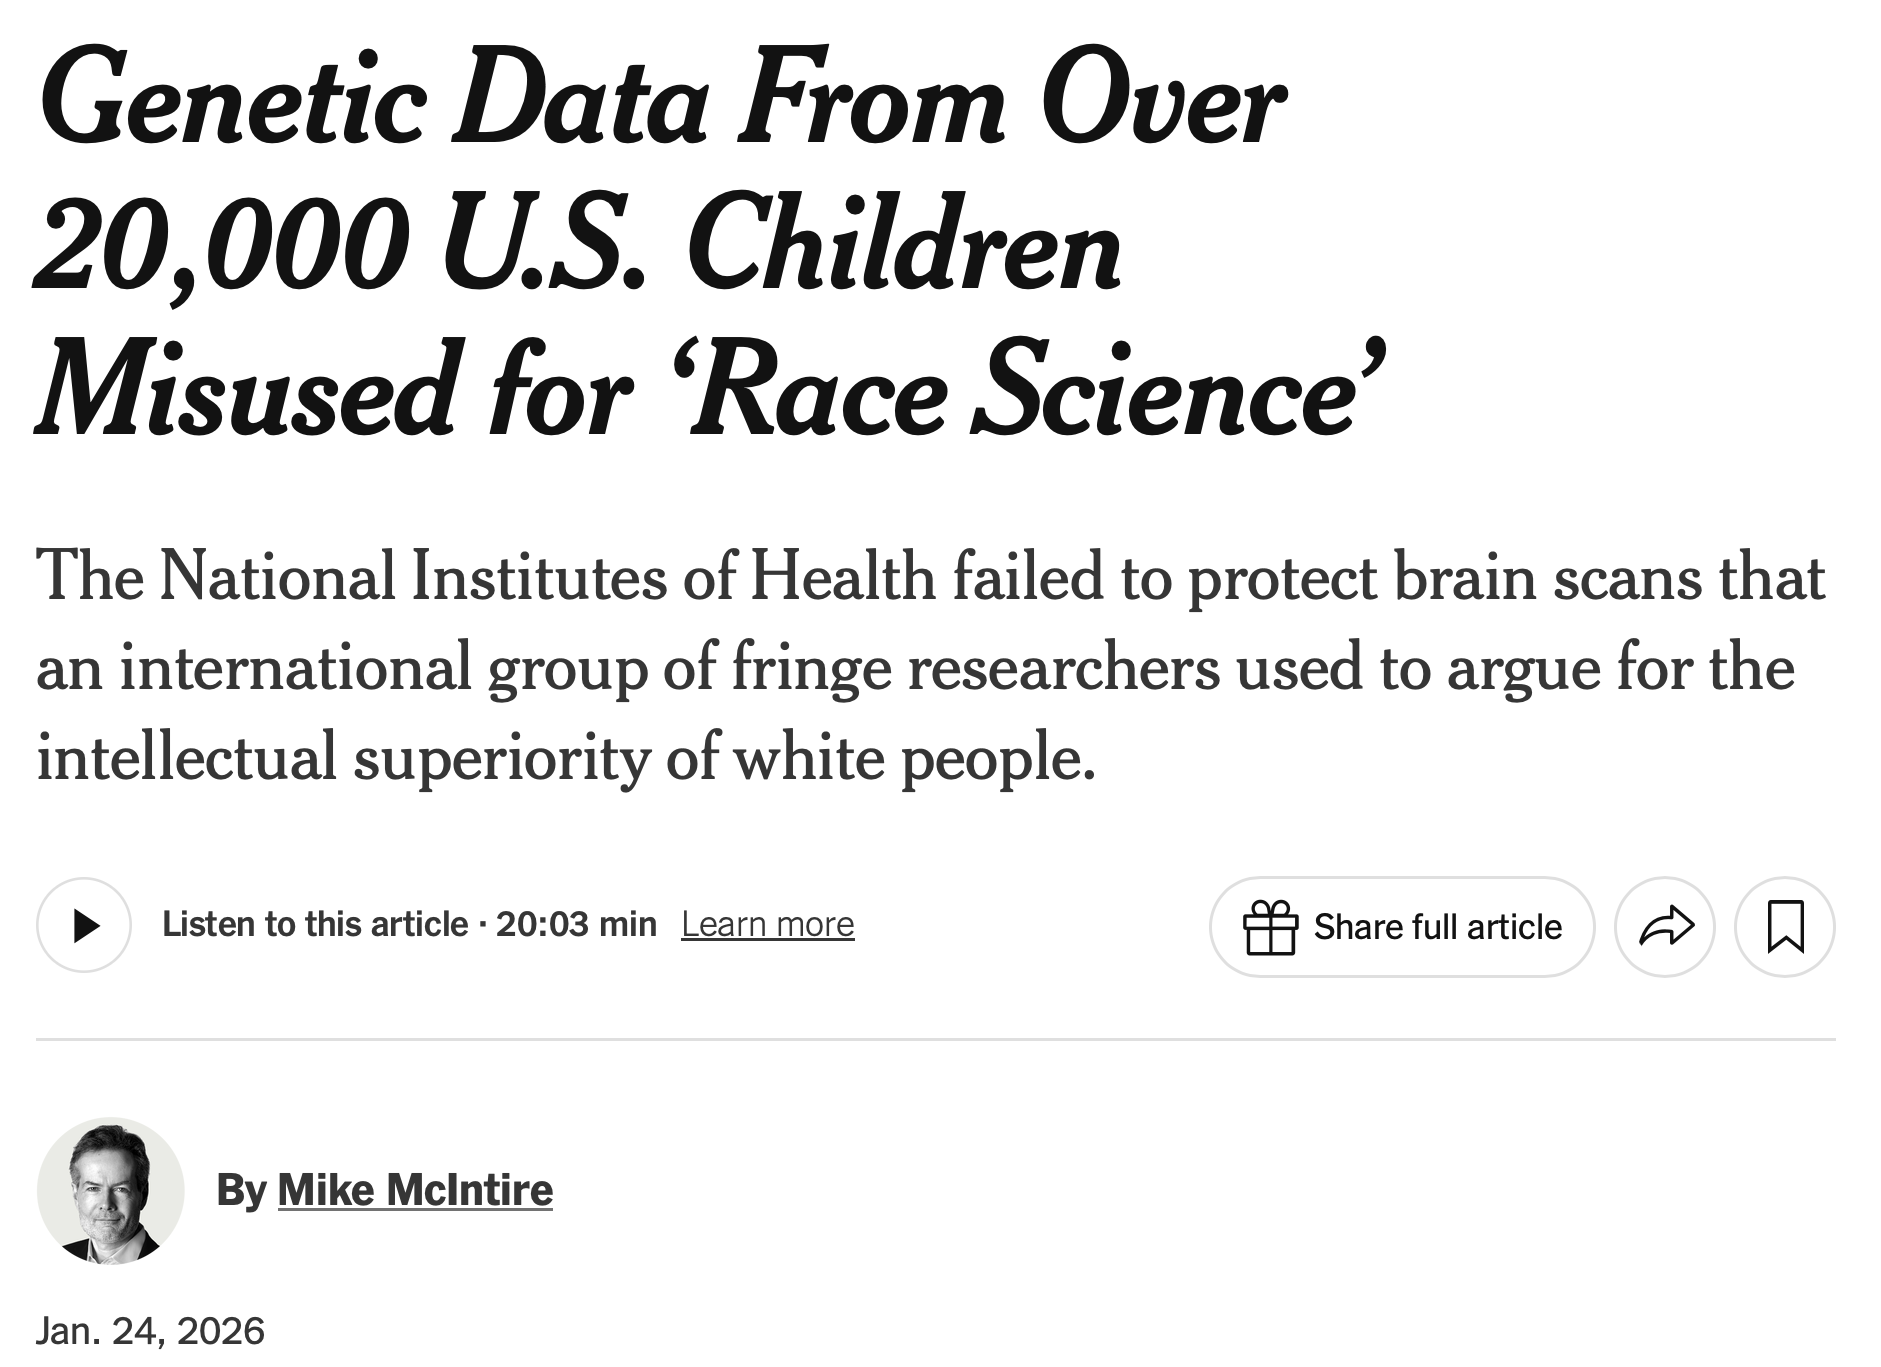
Genetic, cognitive, and brain-imaging data from >20,000 children enrolled in the federally funded Adolescent Brain Cognitive Development Study was obtained and misused by researchers promoting “race science”.
They published at least 16 papers claiming biological differences in intelligence among racial groups – mainstream geneticists reject this work as biased and methodologically unsound.
Removing names from a dataset, alone, does not prevent harm.
Research can stigmatize entire communities even when no individual is reidentified, raising questions about informed consent, researcher vetting, monitoring secondary data use, participant notification, and whether institutions have obligations to prevent both individual and group-level harms.
This is especially of concern since social media and AI systems can amplify claims based on pseudoscience.
Every time we use apps, websites, and devices, our data is being collected and used or sold to others.
More importantly, decisions are made by law enforcement, financial institutions, and governments based on data that directly affect the lives of people.
What pieces of data have you left on the internet today?
Think through everything you’ve logged into, clicked on, checked in, either actively or automatically, that might be tracking you. Submit as many as you can think of.

Go to wooclap.com and use the code UDHRUEH.
Do you know where that data is stored? Who can access it? Whether it’s shared with others?
What are you OK with sharing?
Have you ever thought about why you’re seeing an ad on Google?
Homework: Try to figure out if you have ad personalization on and how your ads are personalized.
Which of the following are you OK with your browsing history to be used towards?
Some common ways people do this, either intentionally or unintentionally, include:
Claiming causality where it’s not in the scope of inference of the underlying study
Distorting axes and scales or using selective annotations to make the data tell a different story
Visualizing spatial areas instead of human density for issues that depend on and affect humans
Omitting uncertainty in reporting
What conclusion might a reader draw from this headline?
8-hour time-restricted eating linked to a 91% higher risk of cardiovascular death
What does 91% higher risk mean?
The result came from a preliminary observational analysis of more than 20,000 US adults.
Eating duration was estimated from two self-reported 24-hour dietary recalls.
Participants were not randomly assigned to eating schedules.
Diet quality and other possible explanations were not fully accounted for.
The conference abstract had not undergone peer review.
The American Heart Association explicitly cautioned that the association did not show that time-restricted eating caused cardiovascular death.
Important questions to ask:
91% higher than what absolute risk?
Was eating duration assigned or observed?
How was eating duration measured?
What other differences between the groups might explain the association?
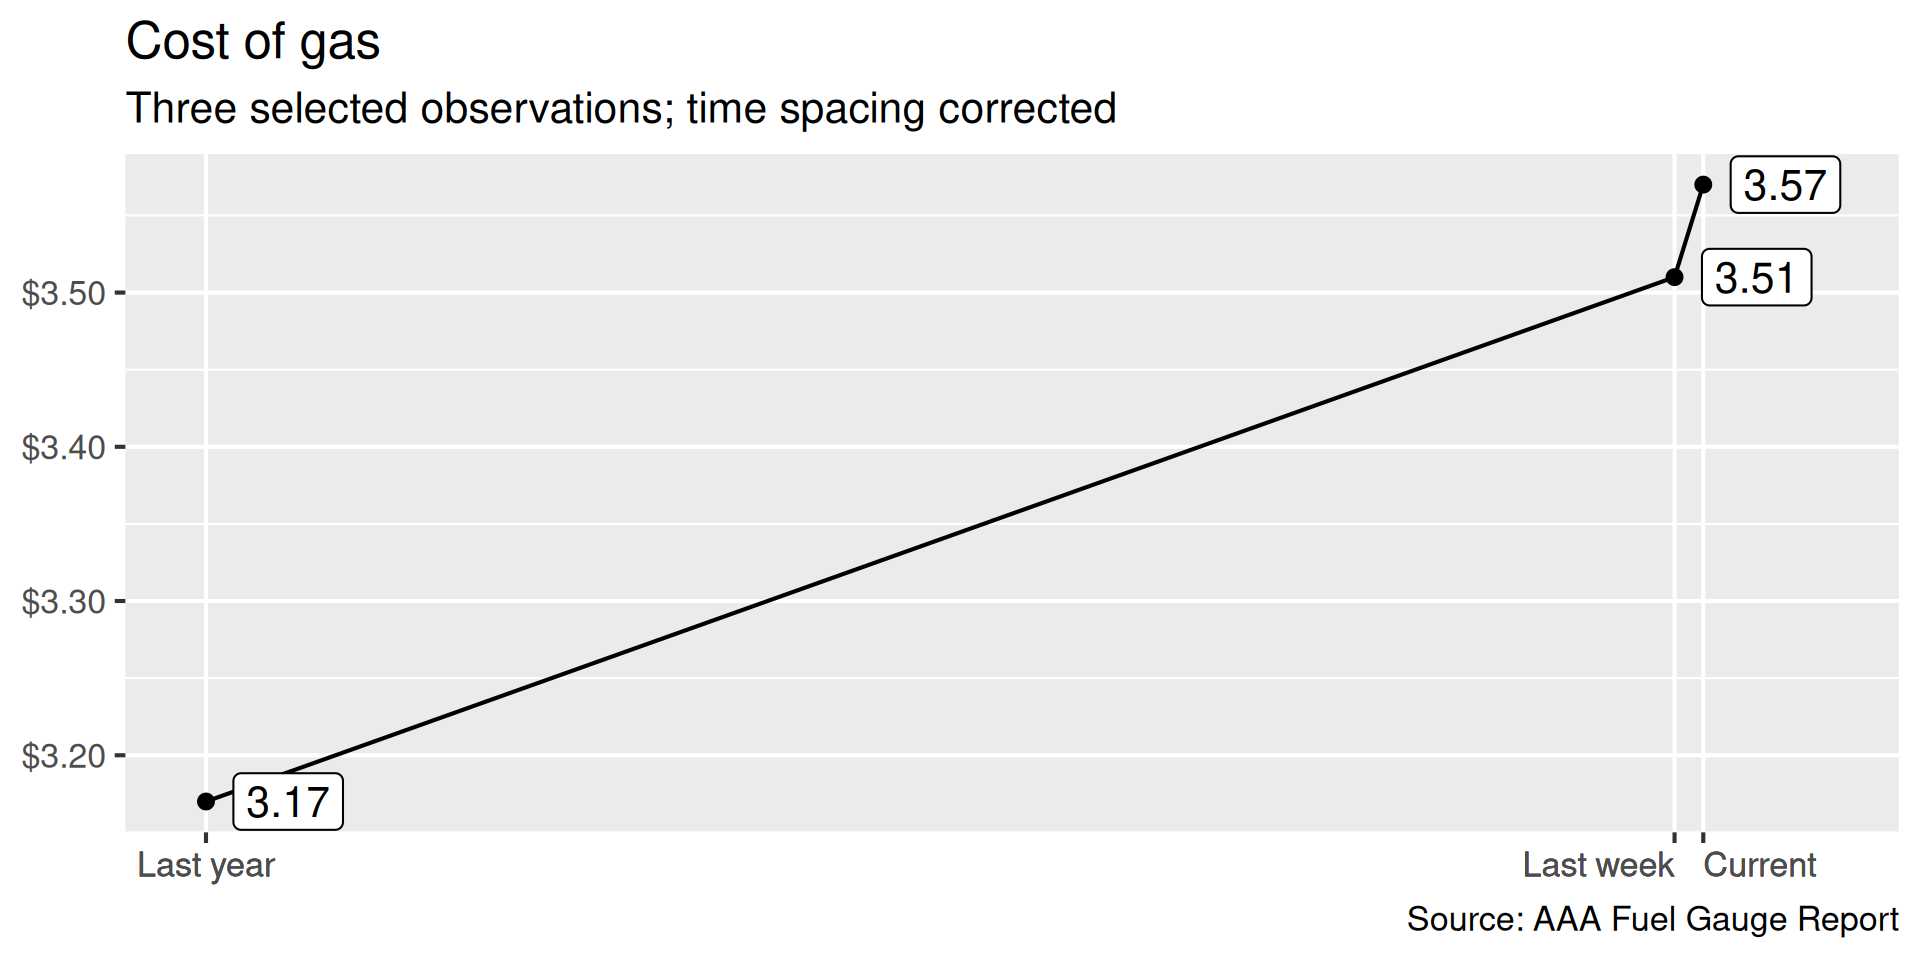
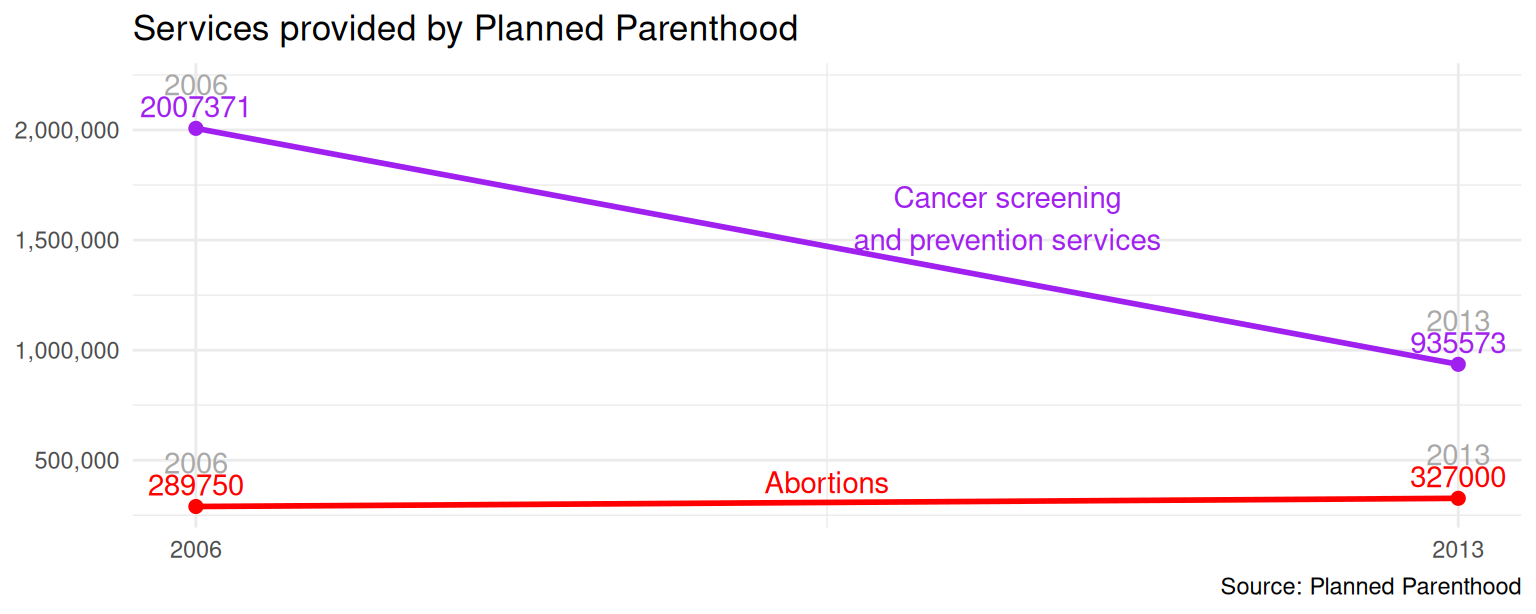
What is the difference between these two pictures? Which presents a better way to represent these data?
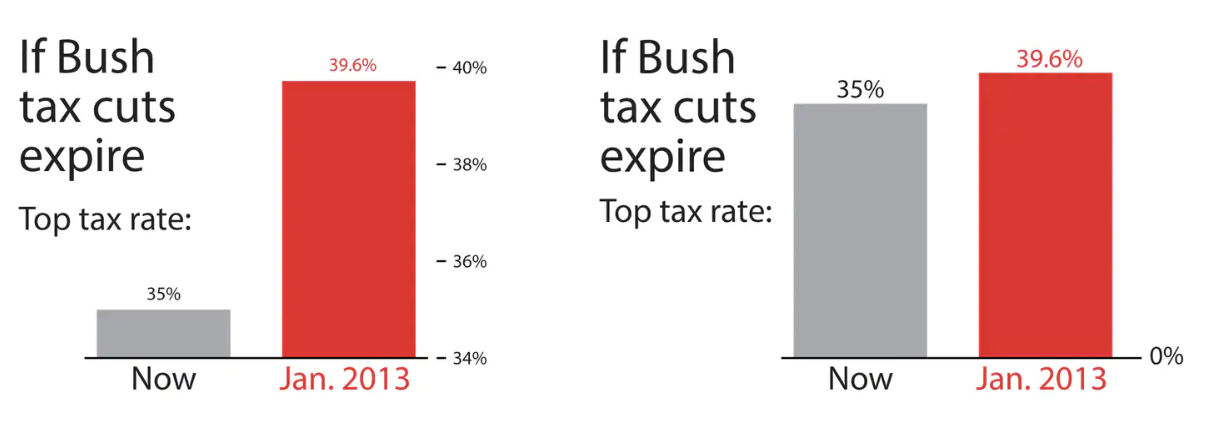
What is wrong with this picture? How would you correct it?
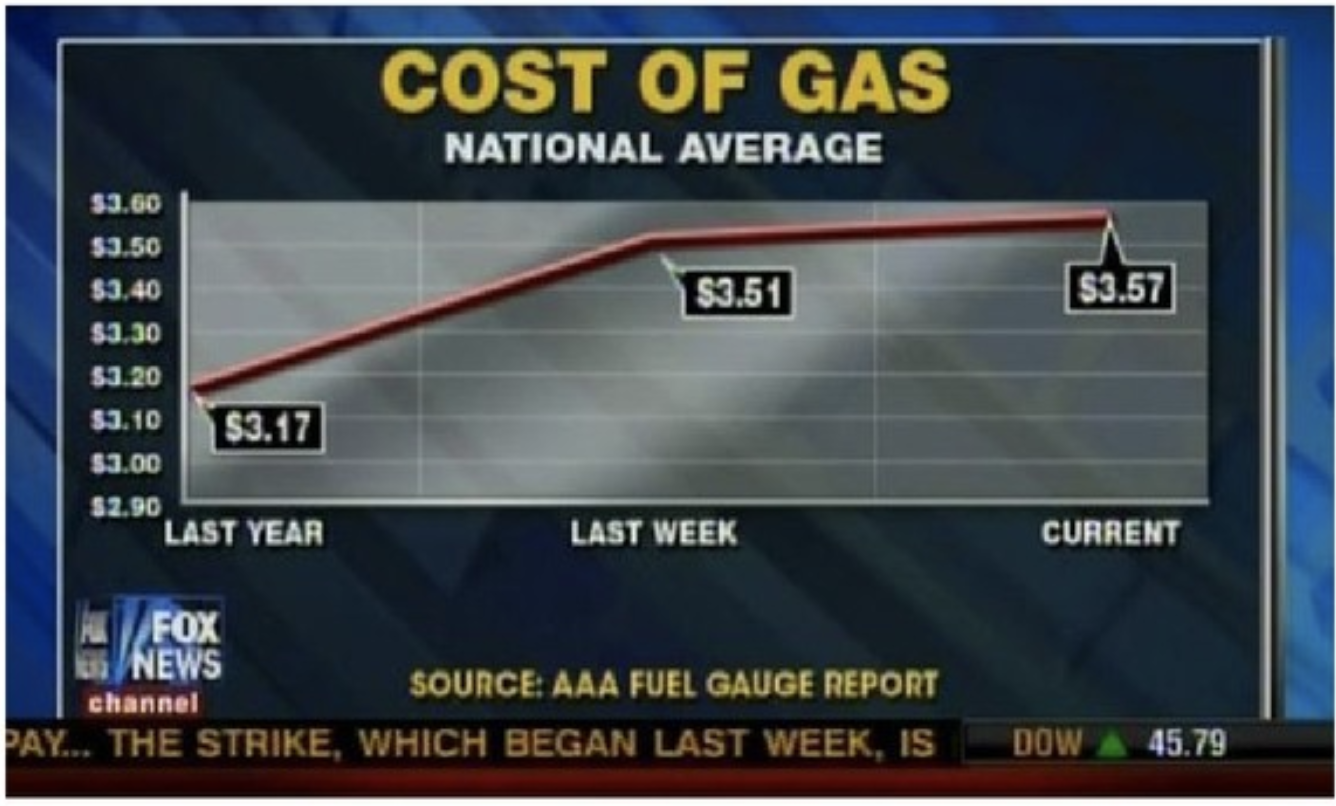
This redraw fixes spacing only; it does not show prices between observations.

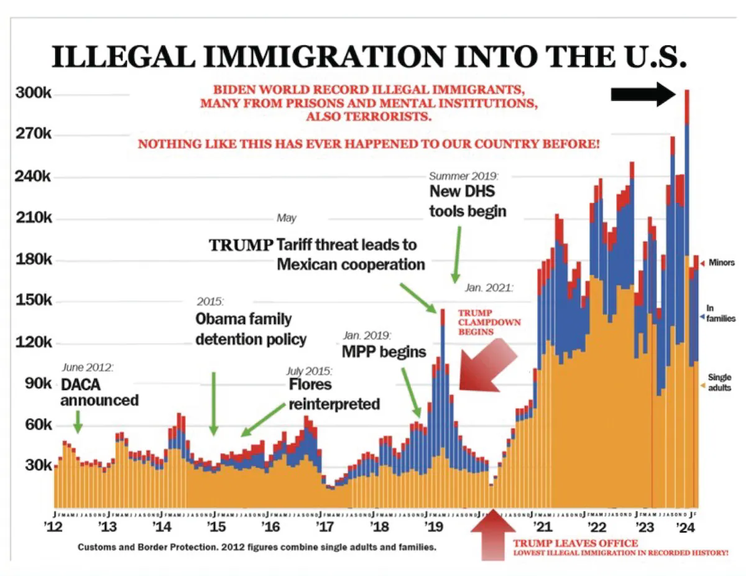
Trump often campaigned in 2024 with a chart on border encounters.
The data values are accurate, but the annotation is not.
The arrow labeled “Trump leaves office, lowest illegal immigration in recorded history” points to April 2020, during the pandemic—not January 2021.
Which part creates the misleading story: the data, the annotation, the selected time point—or all three together?
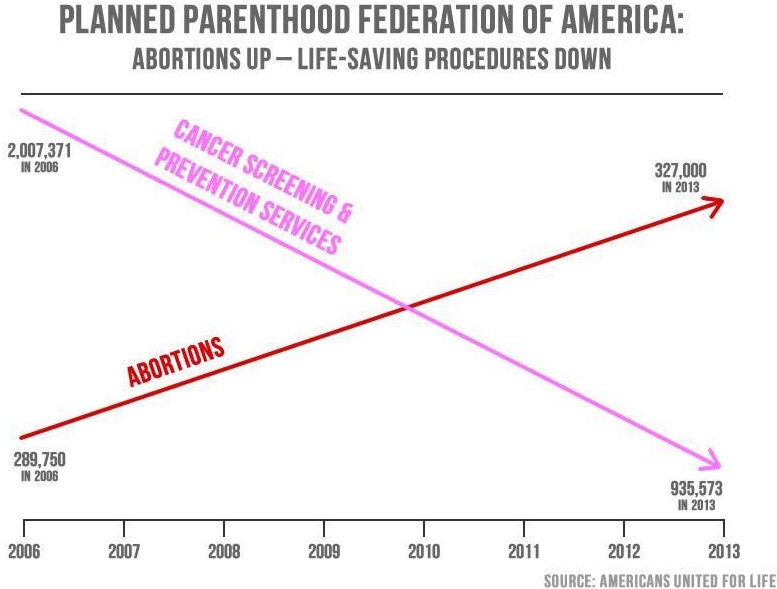
What is this plot telling us?

This redraw fixes axes and scales only; it does not show counts between observations.
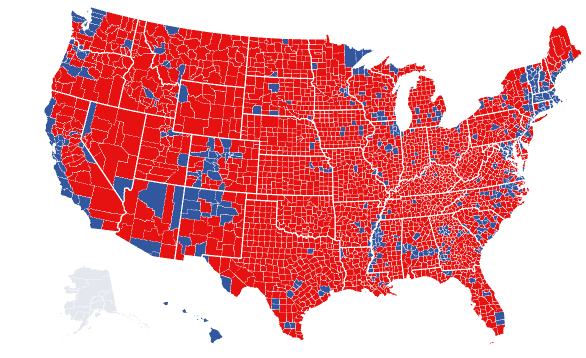
What does this map show?
2024 presidential election results by county: red = Trump, blue = Harris, gray = no data. Source: BallotWire.
What information disappears when every county is assigned one color?

A voting split of 50.1%–49.9% looks the same as a 90%–10% split.
People who voted for the losing candidate disappear from the color encoding.
Differences in turnout within counties also disappear.
The apparent balance depends on whether area represents land, population, or something else.
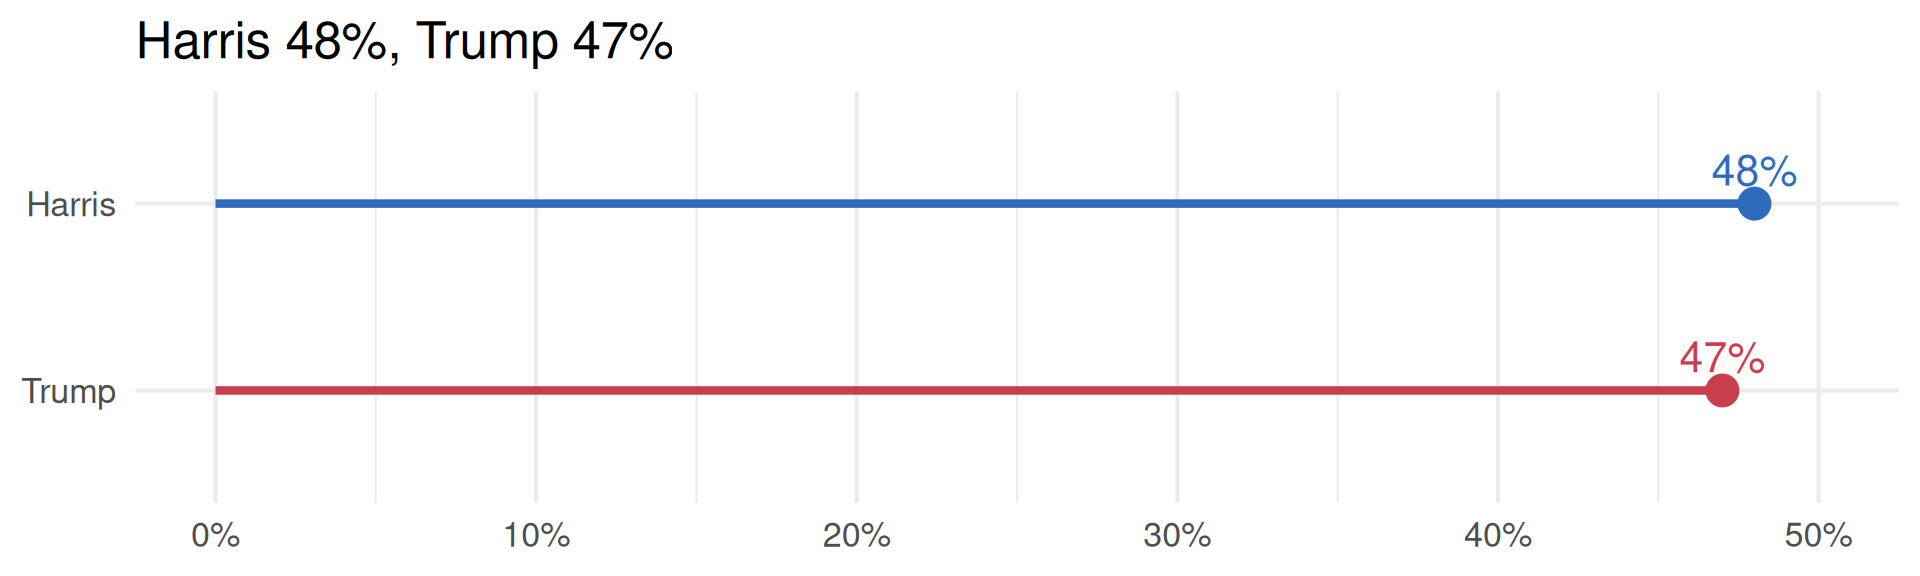
Based on a poll by Cook Political Report, BSG, and GS Strategy Group conducted in July-August 2024, which candidate was ahead in seven swing states combined?

In seven swing states combined, is either candidate clearly ahead?
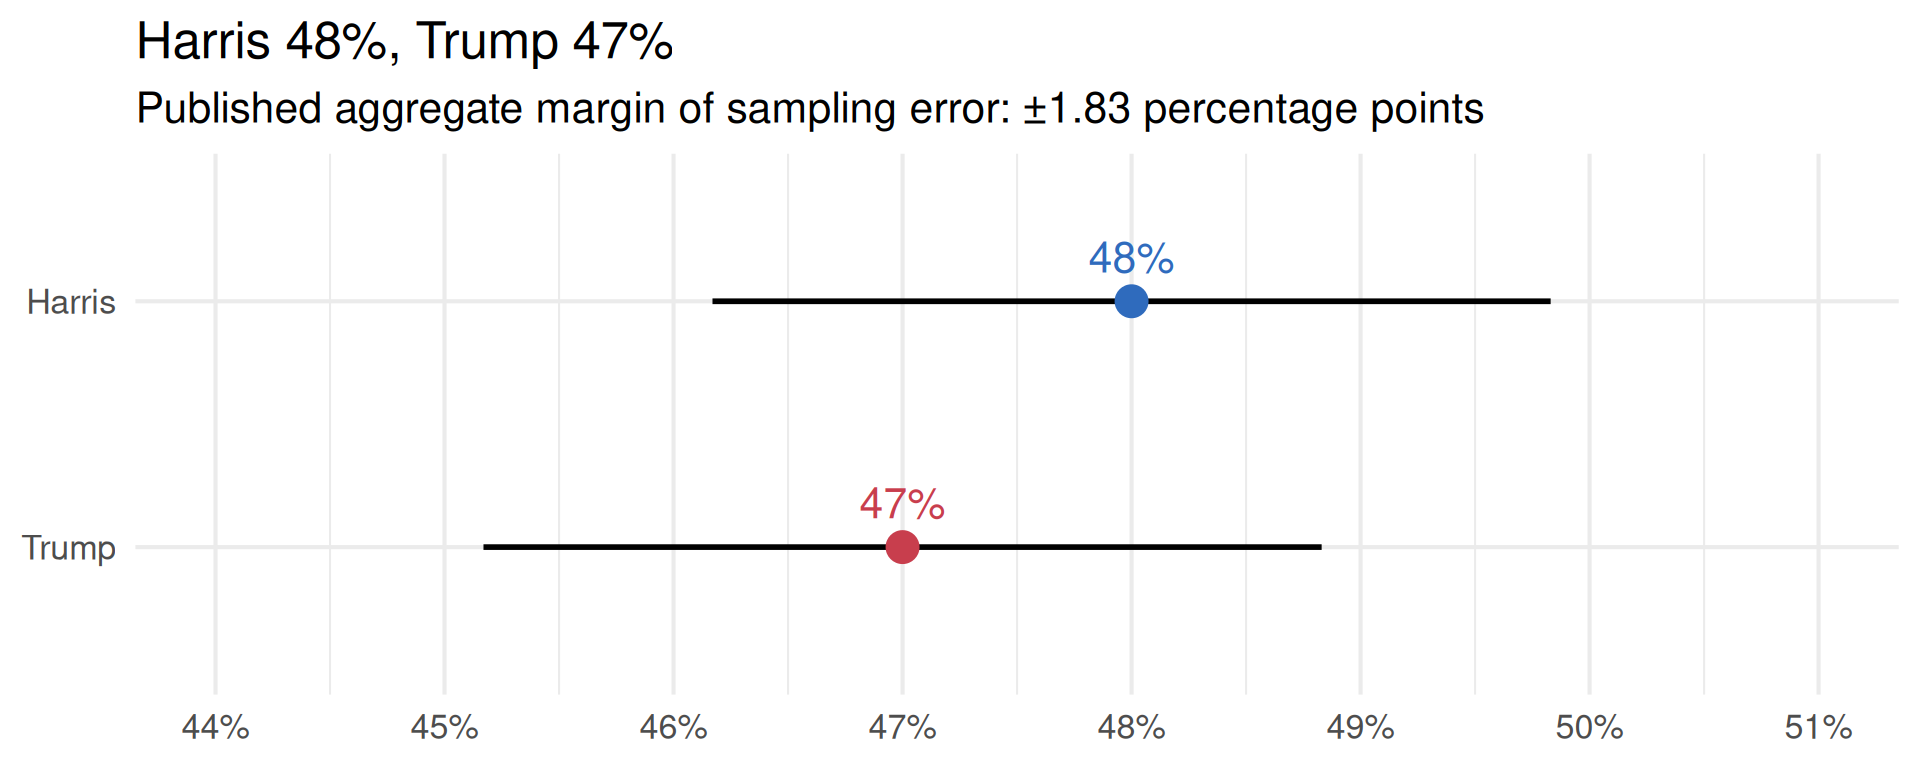
In statistical modeling and inference we talk about “garbage in, garbage out” – if you don’t have good (random, representative) data, results of your analysis will not be reliable or generalizable.
Corollary: Bias in, bias out.
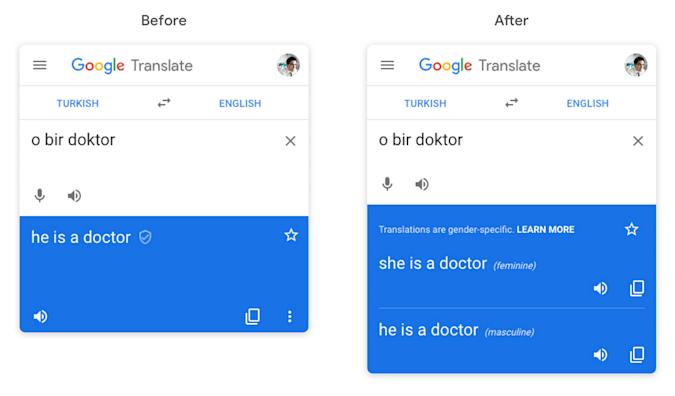
For speakers of languages with grammatical gender (e.g., French, Spanish. etc.), what gender is a table?
What about a doctor?
What might be the reason for Google’s gendered translation? How do ethics play into this situation?
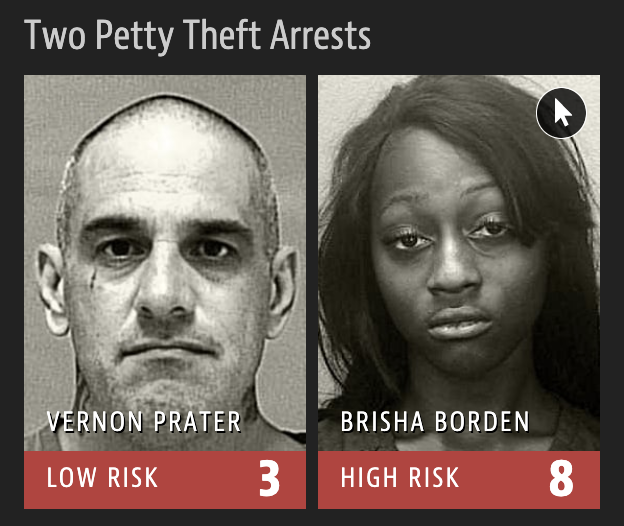
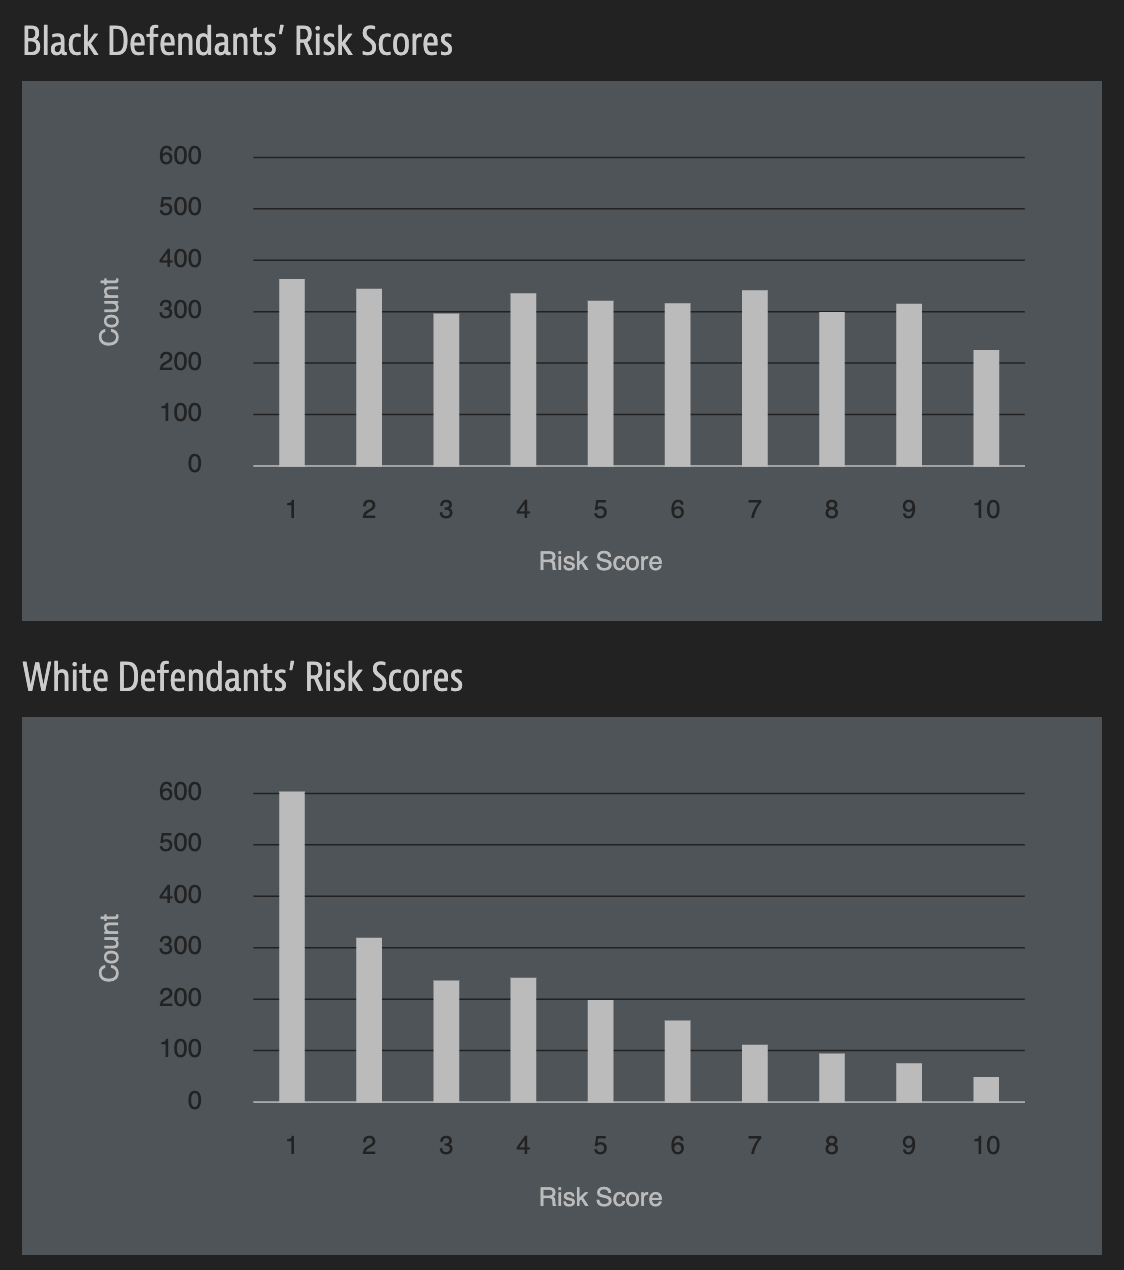
Correctional Offender Management Profiling for Alternative Sanctions (COMPAS)is a proprietary system used to estimate a defendant’s risk of being arrested again.
ProPublica examined more than 7,000 people arrested in Broward County, Florida, and tracked new arrests over the following two years.
COMPAS classified defendants as low, medium, or high risk using criminal records and answers to 137 questions. Race was not one of the questions.
Broward County primarily used the scores for pretrial-release decisions; similar assessments were also used elsewhere for probation, parole, and sentencing.
The scores performed similarly overall for Black and white defendants, but the errors fell differently:
| Black defendants | White defendants | |
|---|---|---|
| Labeled Higher Risk, But Didn’t Re-Offend | 44.9% | 23.5% |
| Labeled Lower Risk, Yet Did Re-Offend | 28.0% | 47.7% |
“Rearrested” means a new arrest within two years, not necessarily a conviction.
Northpointe, the company that created COMPAS, disputed ProPublica’s analysis and defended the tool’s accuracy.
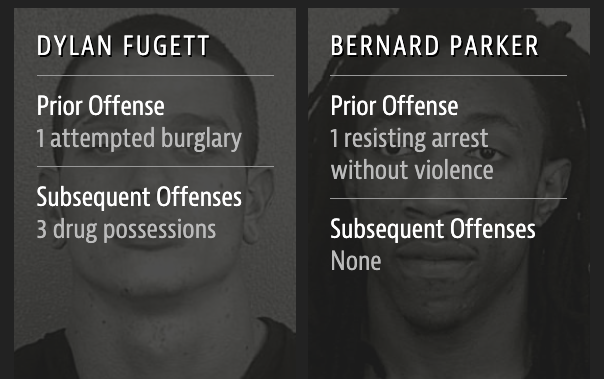
What pattern do you notice in who was assigned a high or low risk score?
These cases illustrate classification errors; the aggregate data provide evidence of group-level disparity.
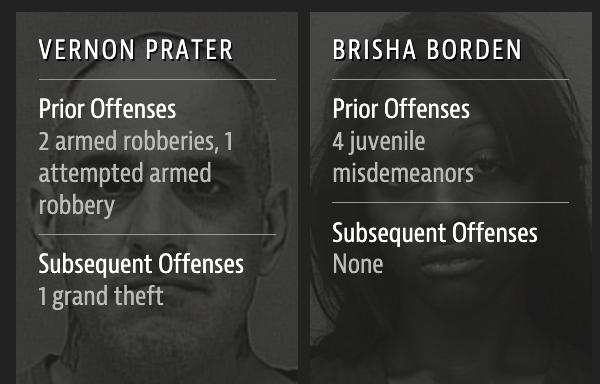
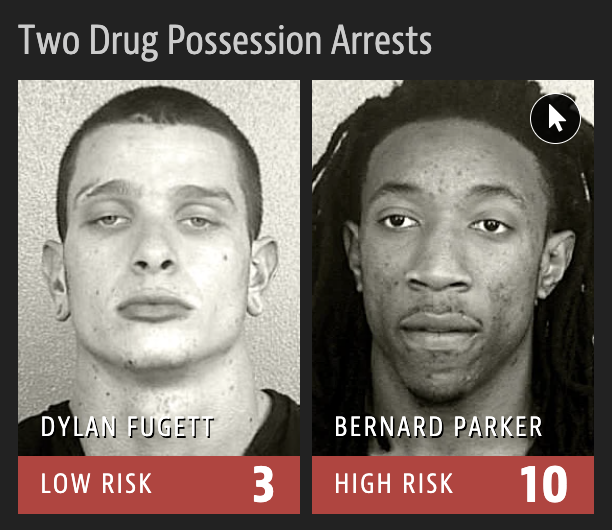
How can an algorithm produce racially unequal outcomes when race is not an input?
Other variables can reflect structural inequalities and act as proxies.
The target is a new arrest, which measures contact with the criminal-justice system—not crime directly.
A proprietary model is difficult for defendants and the public to examine or challenge.
A false positive can restrict someone’s freedom; a false negative can create a public-safety risk. Who should decide how these errors are valued—and who bears them?
At some point during your data science learning journey you will learn tools that can be used unethically.
You might also be tempted to use your knowledge in a way that is ethically questionable either because of business goals or for the pursuit of further knowledge (or because your boss told you to do so).
How do you train yourself to make the right decisions (or reduce the likelihood of accidentally making the wrong decisions) at those points?