Grammar of data visualization
Lecture 3
Warm up
While you wait…
1. Clone your ae repository
Go to the course GitHub organization and clone ae-YOUR-GITHUB-NAME repo to your Positron session in your container.
2. Participate 📱💻
Remember this visualization from the code along video – what was it about?
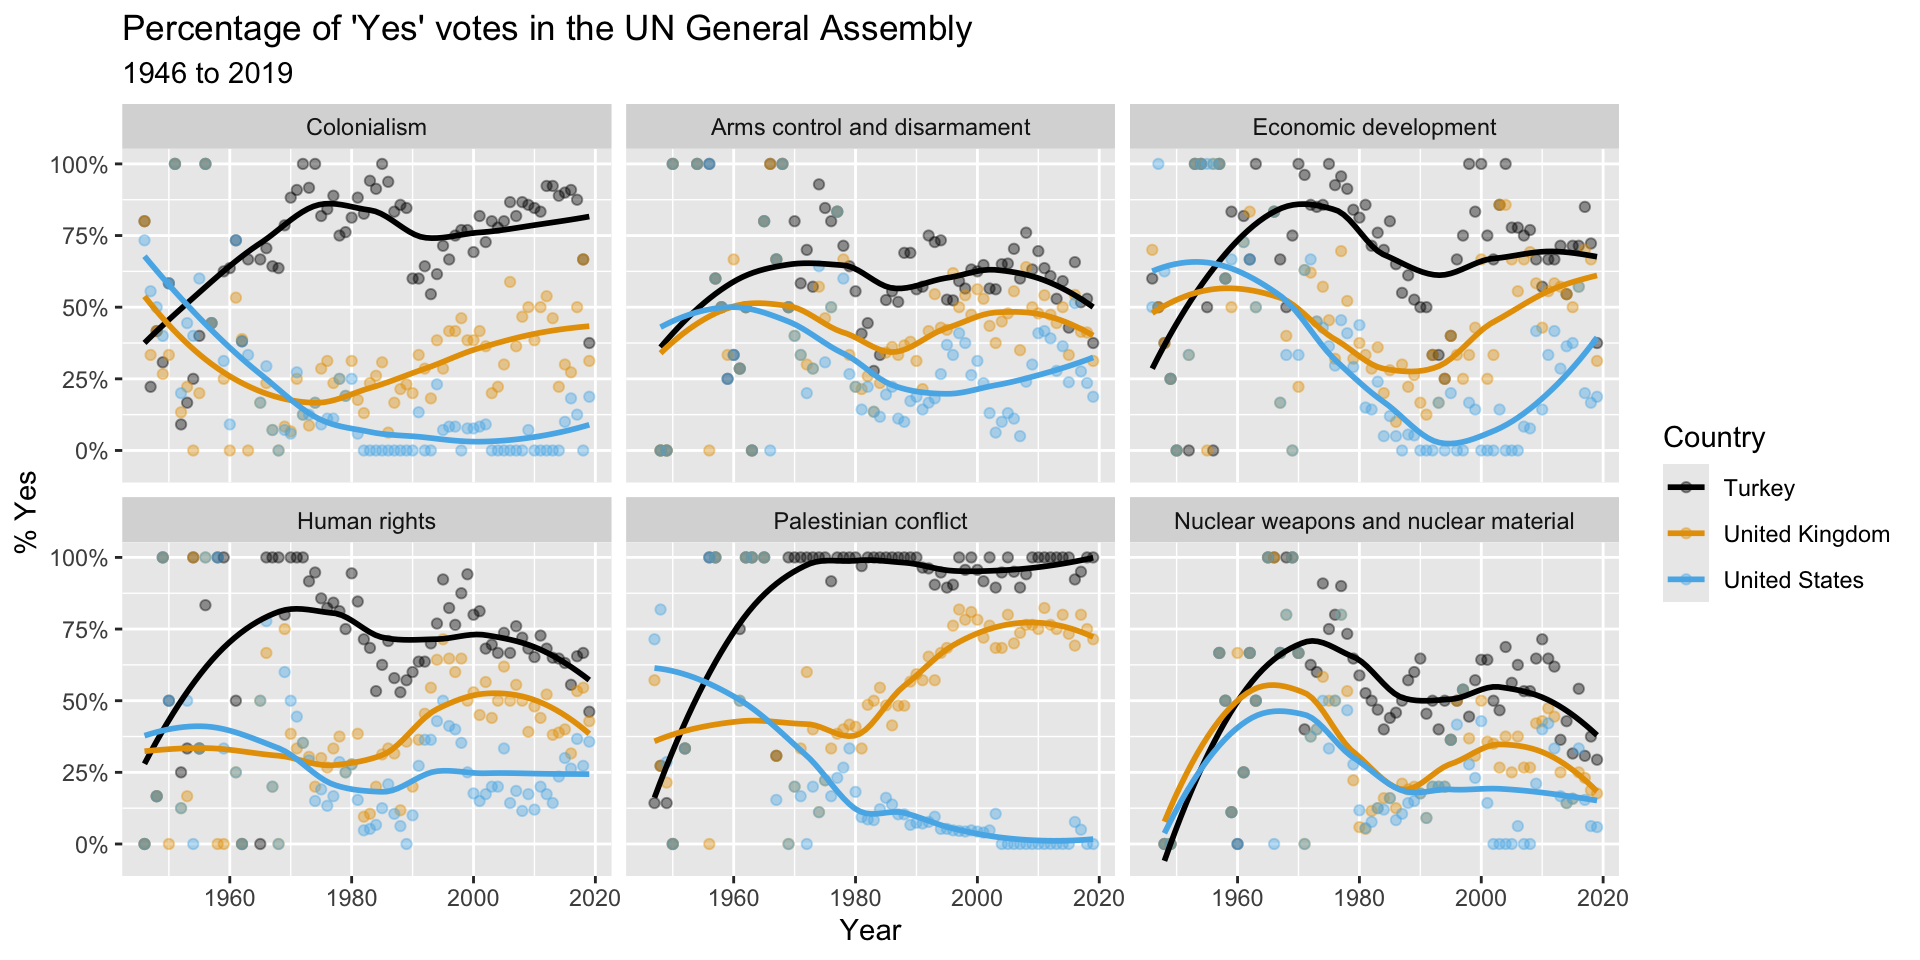
Go to wooclap.com and use the code IOAADOR.
Outline
-
Last week:
We introduced you to the course toolkit.
You cloned your
labrepository and started making some updates in your Quarto documents.You committed and pushed your changes back – at least most of you did!
. . .
-
Today:
You will clone your
ae(application exercise) repository.We will introduce data visualization.
You will work on the application exercise on data visualization, commit your changes, and push them.
Data visualization
Load packages
tidyverse is the collection of R packages designed for data science.
Load the data
gss <- read_csv("data/gss-2024.csv")We can read this as “read the CSV file called gss-2024.csv in the data folder” and save the result as gss.
View the data
gss# A tibble: 3,294 × 9
year marital_status age education_years children happiness health
<dbl> <chr> <dbl> <dbl> <dbl> <chr> <chr>
1 2024 Never married 33 16 2 Not too happy Good
2 2024 Never married 64 16 0 Pretty happy Good
3 2024 Married 69 14 0 Pretty happy Good
4 2024 Never married 19 12 0 Pretty happy Good
5 2024 Divorced 70 13 3 Not too happy Good
6 2024 Married 53 14 2 Pretty happy Good
7 2024 Married 48 13 6 Pretty happy Good
8 2024 Divorced 30 14 1 Not too happy Good
9 2024 Married 60 14 2 Very happy Good
10 2024 Never married 25 12 0 Pretty happy Good
# ℹ 3,284 more rows
# ℹ 2 more variables: employment_status <chr>, party_id <chr>Variables in our extract
| Variable | Description | Type |
|---|---|---|
marital_status |
Current marital status | Categorical |
age |
Age in years | Numerical |
education_years |
Completed years of education | Numerical |
children |
Number of children; 8 means 8 or more | Numerical |
happiness |
Self-reported happiness | Categorical |
health |
Self-reported general health | Categorical |
employment_status |
Current employment status | Categorical |
party_id |
Party identification | Categorical |
Start with a question
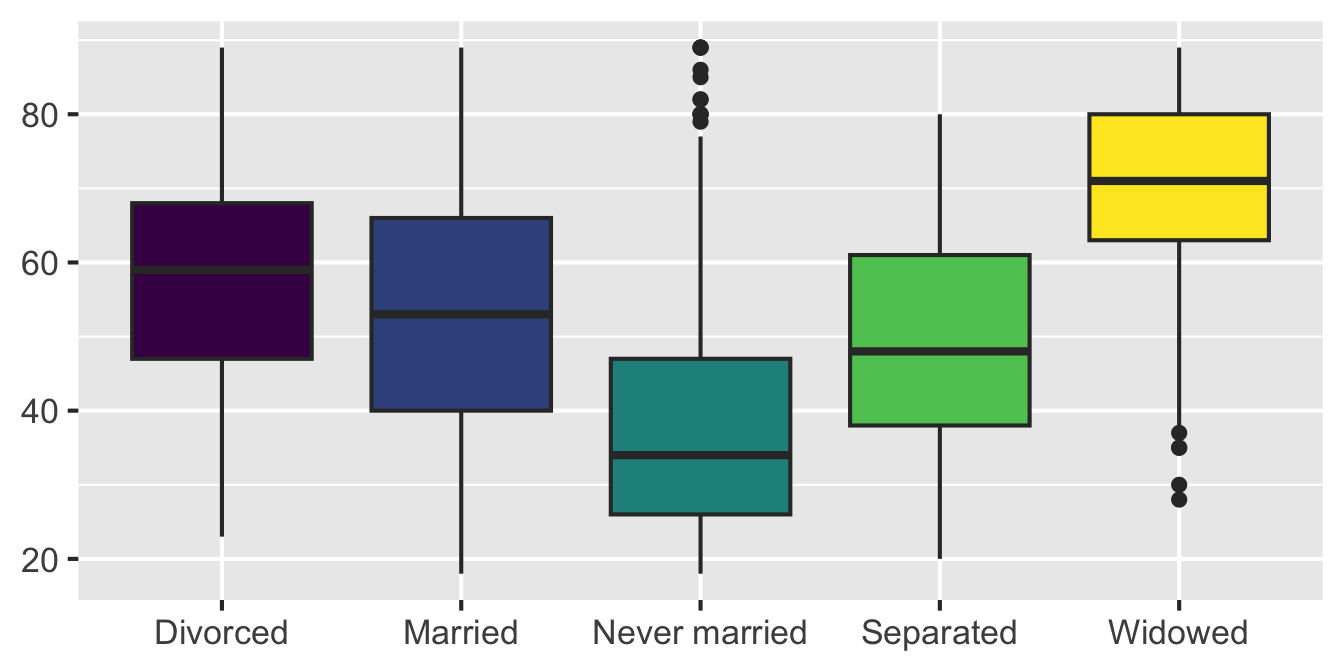
How does age vary across marital-status groups?
Before writing code:
- Which variables do we need?
- What type is each variable?
- What kind of plot might answer the question?
Age by marital status
ggplot(gss, aes(x = marital_status, y = age, fill = marital_status)) +
  geom_boxplot(show.legend = FALSE) +
  labs(
    title = "Age varies substantially across marital-status groups",
    x = "Marital status",
    y = "Age (years)",
    caption = "Source: 2024 General Social Survey (GSS), NORC"
  ) +
  scale_fill_viridis_d()
Warning: Removed 94 rows containing non-finite outside the scale range
(`stat_boxplot()`).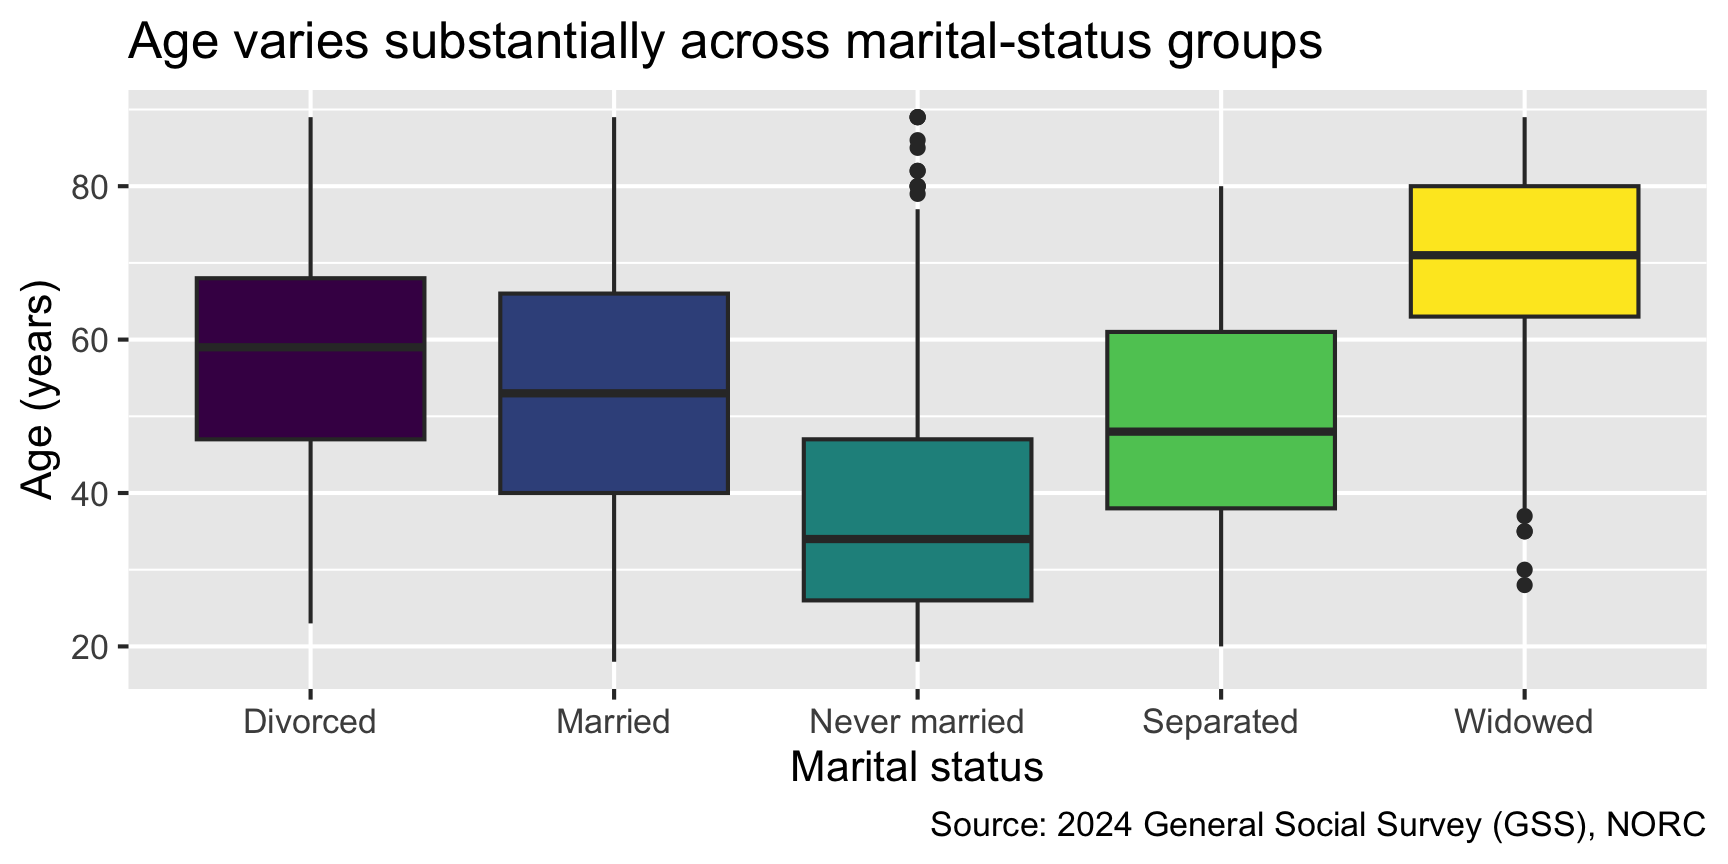
Participate 📱💻
The plot was created, but R displayed the warning below. What happened to the 94 observations?
Warning: Removed 94 rows containing non-finite values
outside the scale range (`stat_boxplot()`).
Go to wooclap.com and use the code IOAADOR.
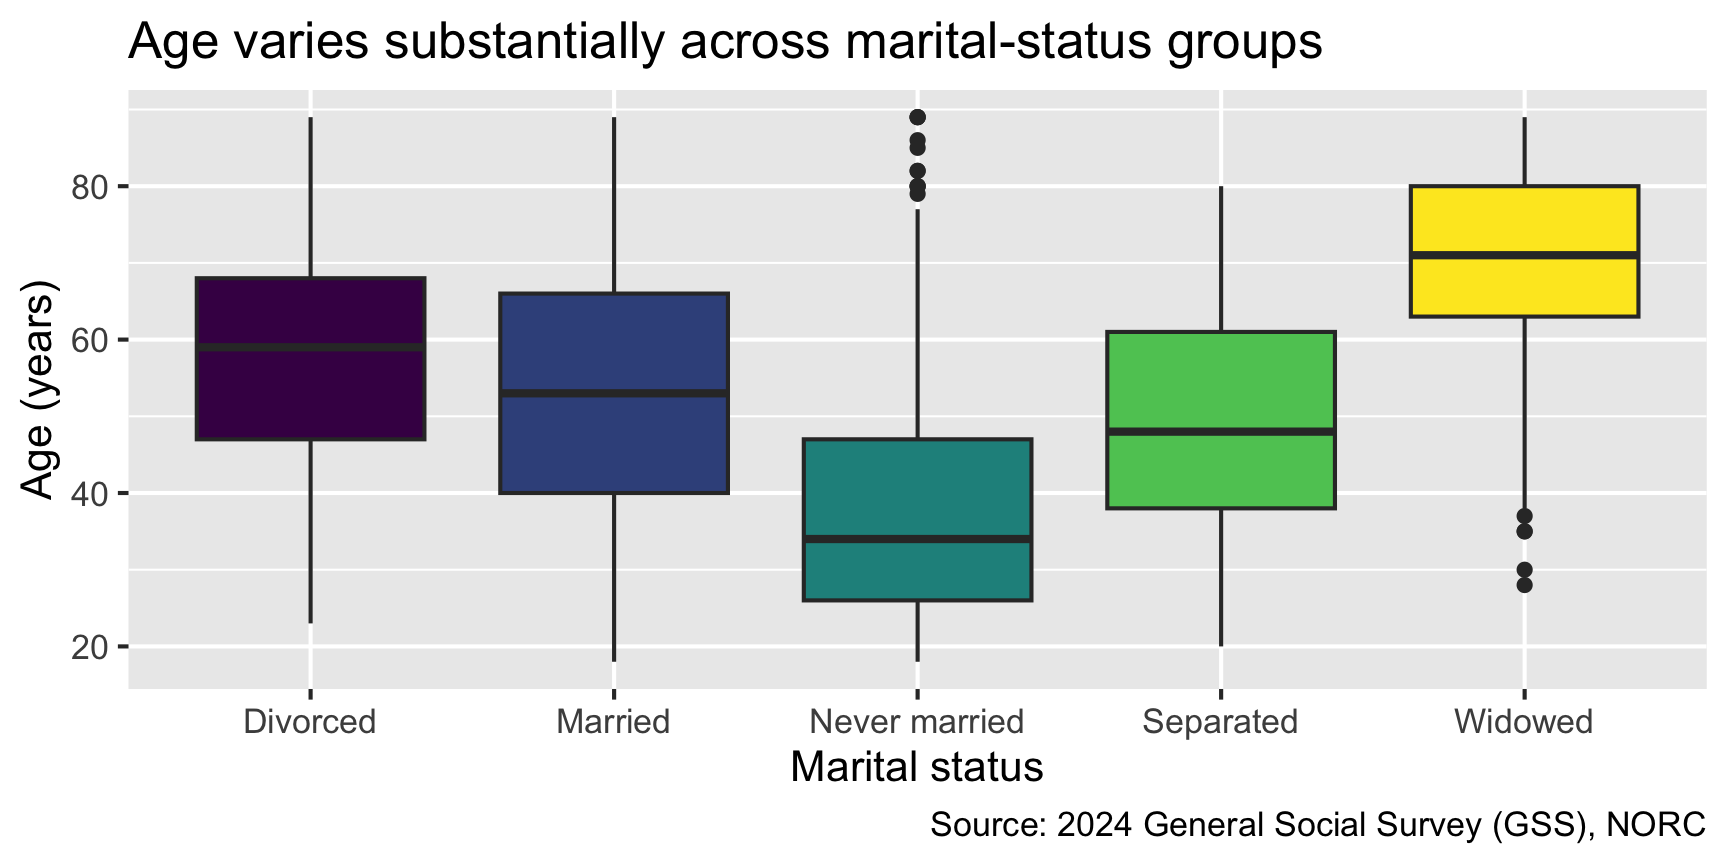
Interpret the plot
With a partner:
- Which group has the highest median age? The lowest?
- Which groups have the greatest variability?
- What does one box summarize?
- Can this plot tell us whether marital status causes differences in age?
Plot autopsy
ggplot(
  data = gss,
  mapping = aes(x = marital_status, y = age, fill = marital_status)
) +
  geom_boxplot() +
  labs(...) +
scale_fill_viridis_d()- 1
- The data to visualize
- 2
- The variables mapped to visual properties
- 3
- The geometric object used to represent the observations
- 4
- The plot labels
- 5
- The scale used to map values to colors
. . .
Which component would you change to plot different variables? Which component controls the variable represented by the fill color?
Mapping and aesthetics
Aesthetics are visual properties such as position, color, fill, shape, size, and transparency.
. . .
For the GSS boxplot:
aes(
  x = marital_status,
  y = age,
  fill = marital_status
)| Variable | Aesthetic |
|---|---|
marital_status |
x position |
age |
y position |
marital_status |
fill color |
Map a variable; set a value
Map: fill varies with a variable, so ggplot2 creates a legend
geom_boxplot(aes(fill = marital_status))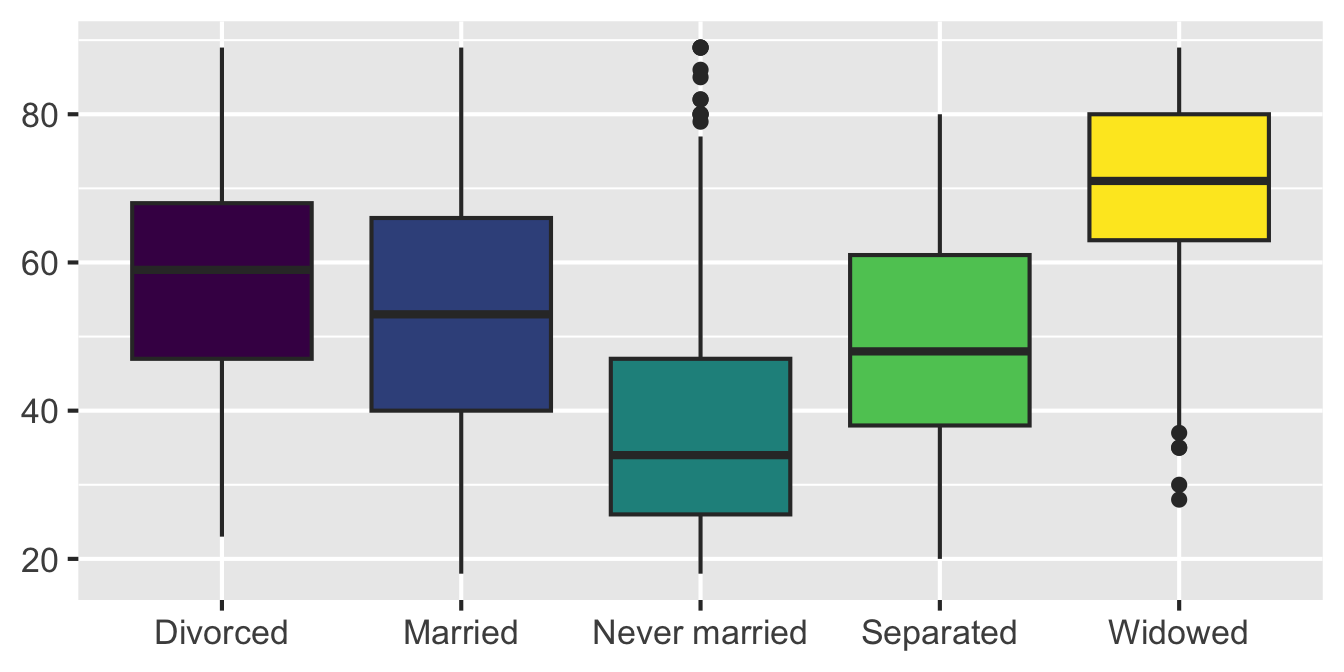
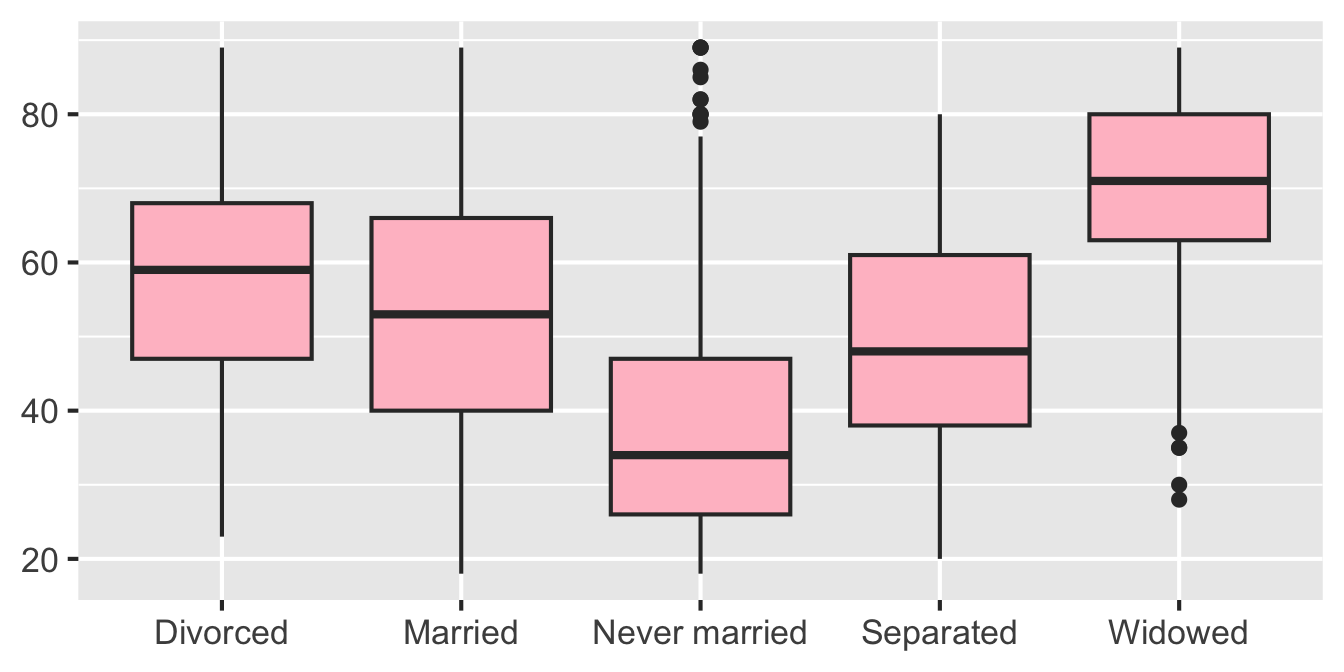
Variables belong inside aes(); fixed visual choices belong outside it.
Grammar of graphics
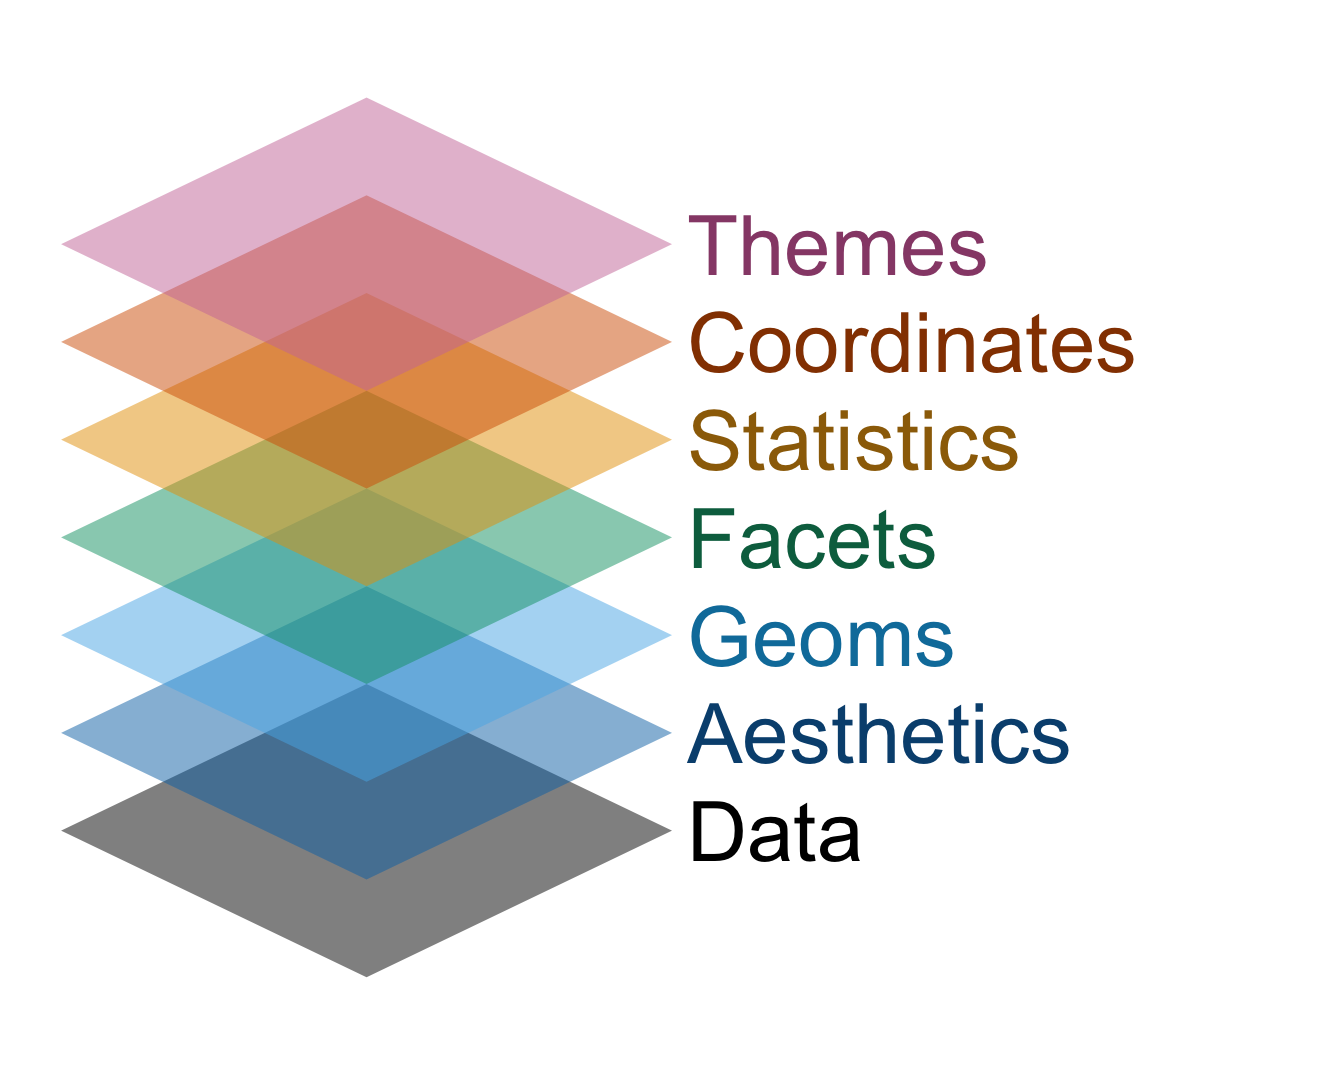
When building or reading a plot, work through the layers as if they’re a checklist.
Not every plot needs every component, but each component is a separate decision.
Application exercise
Let’s get laptops out!
Go to the course GitHub organization and clone
ae-YOUR-GITHUB-NAMErepo to your Positron session in your container.Open
ae-01-gss-dataviz.qmdin Positron and follow the instructions to complete the application exercise.